Tag: home-featured

Control tag: posts with this tag appear in the homepage Featured section.

  • OnPath:  A hiking-app that changed my perspective

    OnPath: A hiking-app that changed my perspective

    I wanted to build a hiking app. It changed how I think about my work.

    I spent about four years working on a watch I built myself. Mostly in the evenings, alongside my job. A black dot appearing on the E Ink display, an LED lighting up, a sensor finally working: those were small successes that gave me a lot of pleasure.

    Recently, I gave the code I had written over those years to an AI agent and asked it to look for bugs and other problems. About half a minute later, it returned a list of roughly 15 points. When I checked them, I had to admit that some were valid findings. There were places where I had not been particularly careful.

    It was impressive. And a little sobering.

    My background is in IT, and I now work in finance, reporting and data analytics. I have been exploring AI closely since I first tried ChatGPT. Even so, my own projects have surprised me in ways that product demonstrations never quite did.

    I wanted to find out what AI could already do. Along the way, I came to understand more clearly where my own experience still matters.

    Three projects that changed my expectations

    My first larger experiment was called “Before We AI”. I wanted to check whether the data were suitable for a particular analysis in the first place. Were the terms clear? Did the tables fit together? Was information missing that would leave the AI guessing?

    My idea was to build a largely deterministic set of rules. Check the prerequisites first, then let the AI do its work. Even where AI helped identify relationships between tables, fixed rules were supposed to validate the result.

    My comparisons did not produce a clear winner. Both the rules and direct AI analysis missed errors and got many things right. The rules also required a lot of manual confirmation. I had underestimated how well AI, given enough context, could identify relationships and work out what needed checking.

    These were limited experiments of my own. But they were enough for me to put the project on hold and question some of my assumptions.

    Next came “Have I Been Here?”. The Android app uses location information in my photos to check whether I have visited a place before. I built an initial version with Claude Code within two days. Along the way, I learned a great deal about Kotlin, Android, user interfaces, testing and releasing an app.

    Then came Tirol.

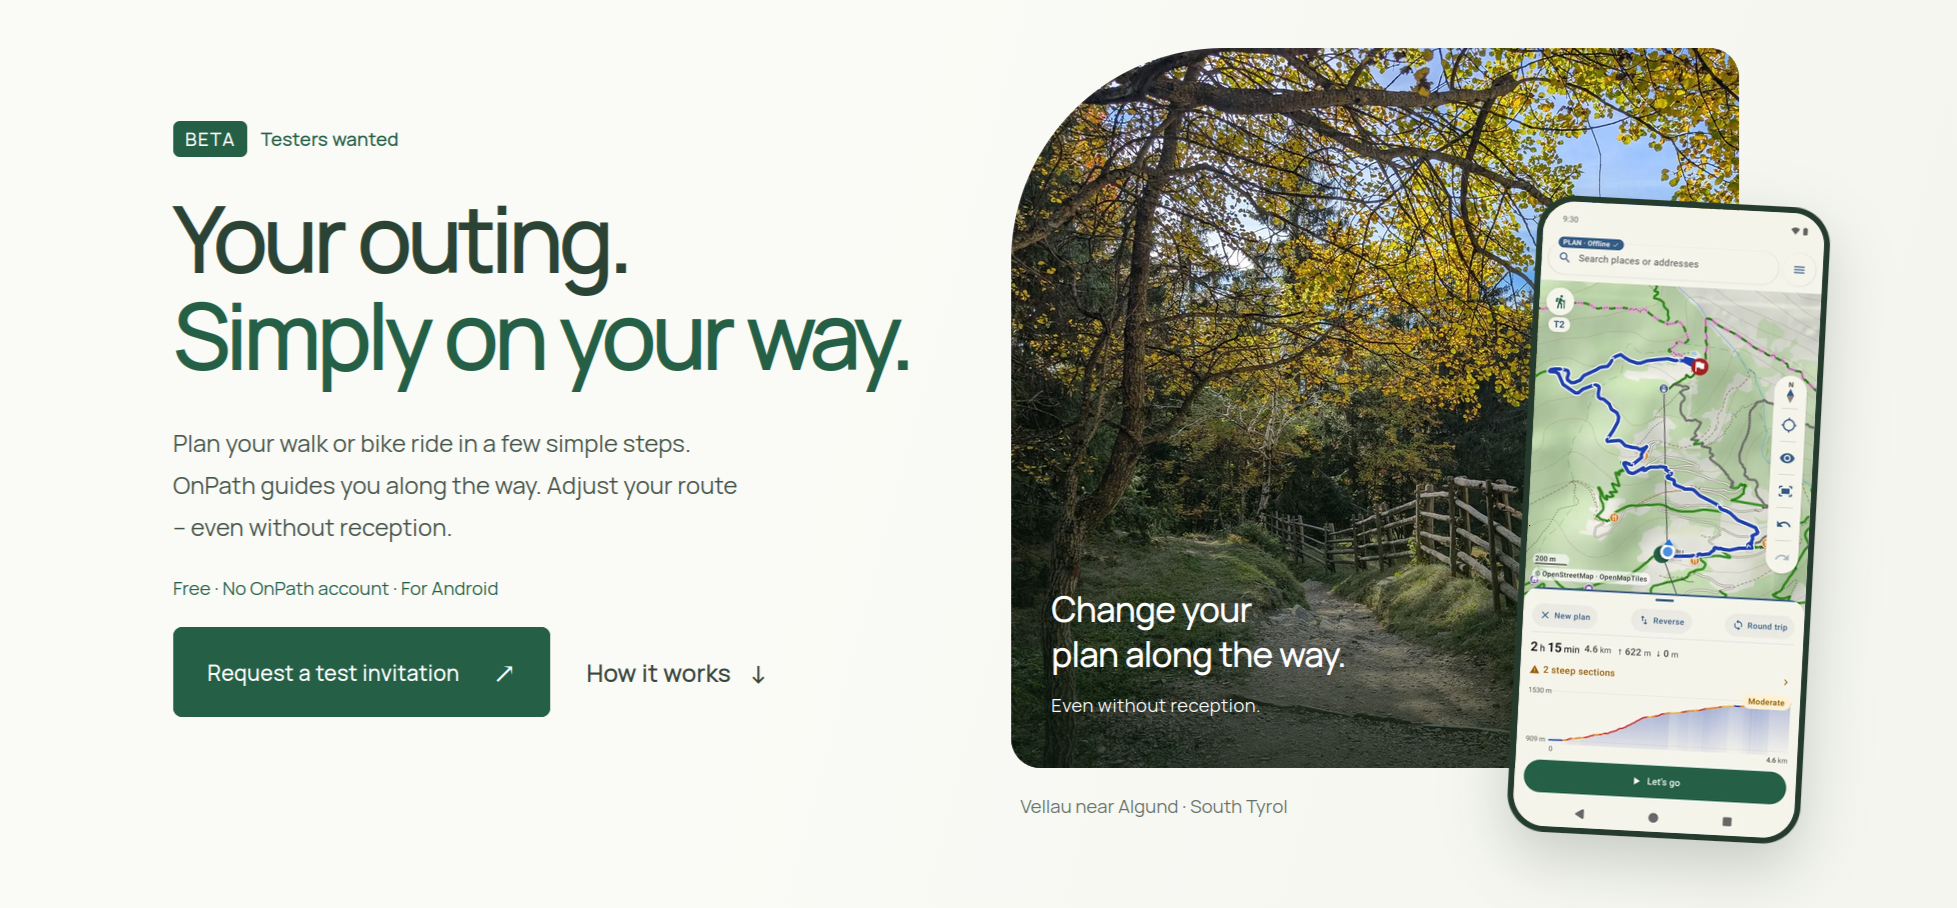
    I have enjoyed using Komoot for many years. On one hike, my planned route suddenly disappeared, and without a signal I could not replan it. That made me wonder: could I use AI to build an app that handled situations like this the way I wanted?

    That was the beginning of OnPath. I was already using it to hike and try out the navigation during the holiday. Back home, I added more features and prepared it for other people to use. An initial test is now running through Google Play.

    Building it was often easier than deciding what was right

    What surprised me was how much help was available beyond writing individual functions. The AI proposed an architecture, considered edge cases and found solutions I would not have thought of myself.

    One example is BRouter, the open-source routing software. OnPath uses it on the phone, and the browser planner is built on the same routing foundation. I did not have to design a second routing system.

    Later, when I wanted a 3D flyover along a planned route, I had a first working version in about half an hour. Previously, just getting familiar with the subject would have taken me considerably longer.

    The user interface was a more persistent challenge. When is a button easy to understand? What should be allowed to change during navigation? How do you prevent accidental input while the phone is in a pocket? Having a function that works technically does not answer those questions.

    My way of working changed too. At first, I had individual pieces of code written in a development environment. Later, I gave an agent larger tasks in a terminal. Eventually, several agents were working on the app, browser planner, website and marketing, coordinated through GitHub.

    At times, it felt like having a development team of my own. I could request substantial changes while also working on small details. During hikes, I dictated observations into my phone. Later, I had a new version built and installed it through the test app’s update function.

    Sometimes, only a few minutes separated an idea on the trail from a change I could try out.

    Can anyone do this now?

    I need to write less and less of the code myself, and understand more and more clearly what I actually want to build.

    I still had to know what I wanted to achieve. I had to define requirements, assess architectural proposals, spot contradictions and test the results. Sometimes, I had to stop an approach because the agent was getting stuck in a solution that missed the underlying problem.

    Finding the right level of detail was particularly demanding: enough guidance to get a suitable result, and enough freedom to leave room for better suggestions.

    That required domain knowledge, IT experience, imagination and persistence. But I no longer needed to know every technical implementation step myself.

    Some of my most demanding architectural discussions were also with an AI. To make those conversations useful, I had to provide my requirements, terminology and previous decisions. The better the context, the more helpful the discussion became.

    For me, that is part of the human side of the “harness”: the framework within which an agent works. Alongside tools and tests, it includes clear goals, accessible documentation and someone who notices when the work gradually drifts away from its purpose.

    What this might mean for finance and analytics

    These experiences have also stayed with me at work.

    An analysis can work technically and still be wrong in business terms. The same term can mean different things in two departments. A table can look complete while containing the wrong set of records. In accounting entries, forecasts or intercompany reconciliations, those differences have consequences.

    People also make mistakes when they describe requirements or develop software. So I am not convinced by a blanket distinction between unreliable AI and dependable human work. I am more interested in how we can check the results and which controls actually work.

    I expect business teams to gain much more scope to create things themselves: analyses, tailored reports and, eventually, clearly bounded workflows carried out by AI agents. Where decisions or accounting entries are involved, permissions, approvals and checks that can be reviewed need to be part of the design from the beginning.

    My attention is shifting as a result. I spend more time thinking about which data and rules are needed, how relationships are described and how to recognise a correct result. Technical implementation still matters. But it takes up less of my own work than it used to.

    The cost is falling. The sense of achievement is changing.

    During the intensive development phase of OnPath, my additional AI subscription spending was around €300 to €400. That is not the full cost of the project. My time, experience, existing hardware and the open-source projects I used are part of it too. Running and maintaining the app will also require work.

    Even so, it has become much easier for me to take a substantial idea and actually try it.

    There is a personal downside to that. When I used to find a bug after many attempts and my program finally worked, I felt proud. Now, I sometimes wait a few minutes, check the result, tick off the task and move on to the next one.

    I can build much more now. Whether it makes me more satisfied is another question.

    That is why I want to hold on to my curiosity and deliberately look for tasks that help me keep learning. I still enjoy software development. That enjoyment is changing, and I do not yet know quite where it will lead.

    For me, OnPath has become both a useful app and a very practical learning experience. I would like to bring what I have learned into my work with finance, analytics and AI.

    If you enjoy hiking or cycling and have an Android phone, you can take a look at onpath.earth and ask to join the test. For me, the project also includes learning how to take an experiment through testing with invited users and eventually make it publicly available.

    My intention is for OnPath to remain free to use. Later, I could imagine a fair charge for additional, optional online services, with some of the proceeds going to charitable causes. AI and servers consume resources, which is another reason I want to be thoughtful about how I use them. I have not decided on the details of that model.

    If this experiment becomes a helpful app, gives me a reason to keep learning and eventually allows me to give something back to others, that would be a good reason to keep going.
  • Before we AI: can you trust the numbers?

    Before we AI: can you trust the numbers?

    Working around finance, reporting, data and large transformation projects, I have seen technology move a long way.

    AI now promises the next step: instead of building another report, people can simply ask questions of company data and get an answer.

    The demos are impressive.

    But there is one thing I keep coming back to:

    Can we trust the numbers?

    Not because the AI cannot calculate.

    Because many of the decisions behind a business number were never really part of the data in the first place.

    • Which of three systems counts when they disagree?
    • Is that export in Controlling the source of truth or simply a copy somebody kept?
    • At what level do we eliminate intercompany?
    • What exactly does “last year” mean in this company?

    And yet a system can produce a number without having explicit answers to any of those questions.

    That is what bothers me.

    It worked without those answers. So somebody — or something — supplied them. Not you.

    And that can be surprisingly difficult to detect.

    If the wrong table is selected, you do not get an error. You get a number.

    The SQL is correct. The arithmetic is correct. The result looks completely normal.

    Your fiscal year runs May to April, but “last year” is interpreted as January to December? You still get twelve perfectly valid months.

    Just not the twelve months you meant.

    And this can easily survive testing. A test may confirm that the system computes what it was told to compute — without establishing that the underlying business interpretation was the right one.

    That is the problem I started working on with before-we-ai.

    The idea is to put a control point in front of the AI answer.

    For a business question such as “show me revenue by entity and month”, before-we-ai makes visible:

    • what that answer depends on;
    • which sources and business rules are being used;
    • what can actually be verified against the data;
    • what somebody in the business still needs to confirm.

    Where something can be tested, it is tested against the data.

    Where it is a business decision — for example which source is authoritative — somebody has to own that decision, with a defined scope.

    And unresolved points stay unresolved.

    The result is deliberately simple:

    Ready.
    Ready with limitations.
    Blocked.

    And if it is blocked, you see why.

    That is what I would want to know before putting an AI-generated number into a management report, a board pack or another business-critical decision.


    The idea behind before-we-ai

    The important part is not another semantic model or another layer of metadata.

    It is making the reasoning behind a business answer visible.

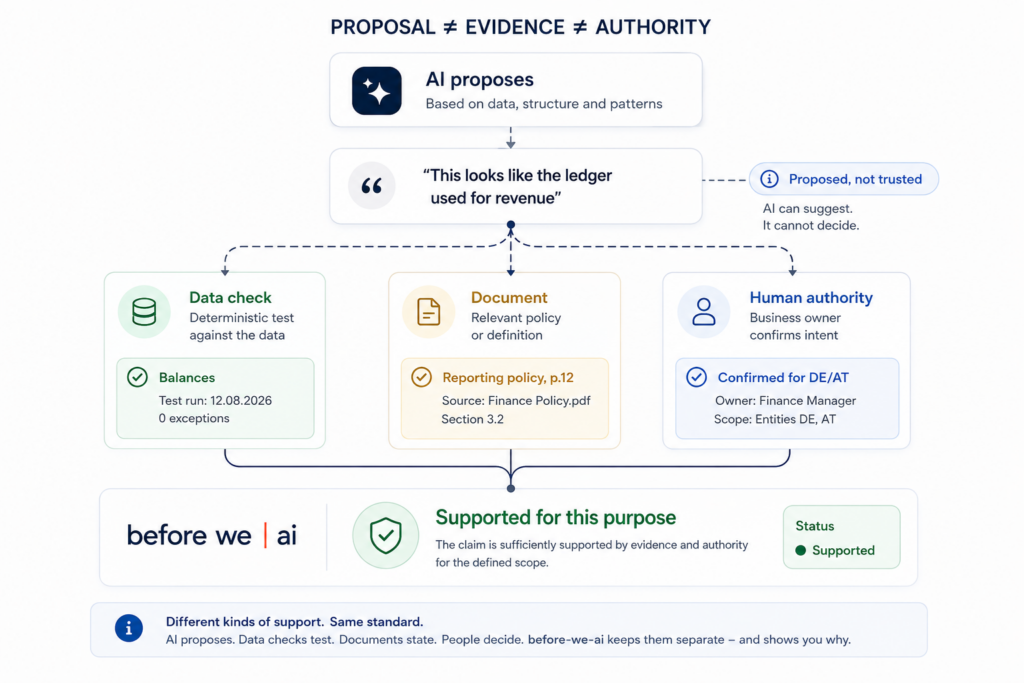
    Diagram showing that revenue by entity and month depends on ledger, entity, reporting period, revenue definition, and intercompany treatment, with readiness status.

    Suppose the system believes:

    This table is the general ledger used for the revenue calculation.

    In before-we-ai, that statement is not silently treated as fact.

    It starts as a claim.

    And a claim can have very different kinds of support.

    The AI may have proposed it because the table name, columns and relationships look plausible.

    A policy document may contain a relevant definition.

    A deterministic test may show that the table balances correctly.

    A finance expert may confirm that this is in fact the ledger used for this reporting purpose.

    These are different things, and before-we-ai keeps them separate.

    That distinction is the core of the project.

    From a claim back to the evidence

    Instead of starting with a number and explaining it afterwards, the system works backwards through what must be true.

    For example:

    Revenue by entity and month depends on the correct ledger.

    That becomes:

    Which source represents the ledger?

    There may be several candidates.

    One could be the actual ERP journal.

    Another could be a reporting export that looks almost identical.

    A third may be an old copy.

    The AI is useful here. It can inspect the available structure and propose likely candidates.

    But it is not allowed to decide that its own proposal is correct.

    The candidates are tested where testing is possible.

    If a supposed journal does not balance, that is strong evidence against it.

    The query that ran, the population tested and the exceptions remain attached to that result.

    If two candidates both survive, the system does not simply choose the one with the nicer table name.

    It leaves the question open.

    Someone has to decide.

    That is deliberately different from asking an LLM:

    Which of these tables is probably the journal?

    The model can help find the candidates.

    It cannot create the authority.


    Not every business rule lives in the data

    Some questions cannot be settled by SQL at all.

    Which price should be used for expected costing?

    Which system is authoritative when two systems disagree?

    Which customers count as intercompany?

    What constitutes revenue for this management report?

    These are not properties waiting to be discovered in a table.

    They are organisational decisions.

    A document may provide the answer. If it does, before-we-ai keeps the connection to the source and the relevant passage.

    If a person has to decide, the confirmation should have a scope.

    Not simply:

    Revenue definition approved.

    But something closer to:

    This definition applies to these entities, for this reporting purpose.

    The idea is to make business knowledge traceable in the same way we already expect technical lineage to be traceable.

    Technical lineage tells us where the data came from.

    This adds another question:

    Why are we entitled to interpret it this way?


    The AI has a deliberately limited role

    I am not trying to solve this by using less AI.

    Quite the opposite.

    AI is very useful for reading documentation, inspecting unfamiliar data, finding relationships, proposing mappings and identifying what should be checked.

    That work can save a huge amount of manual investigation.

    But there is one boundary in before-we-ai:

    The AI can propose. It cannot promote its own proposal into a trusted fact.

    Something that came from the model stays a proposal.

    A deterministic check can provide test evidence.

    A human can confirm organisational meaning.

    A document can provide a traceable source.

    And if none of those settles the point, it remains unresolved.

    The model cannot make the red light disappear by producing a more convincing explanation.


    What the user should see

    Most of this should not look like an AI architecture to the person using it.

    The intended experience is much simpler.

    You ask a business question.

    For example:

    Show me actual P&L by entity and month.

    The system then shows the few things that matter for that answer:

    Ledger of record
    One candidate survives the accounting checks.

    Entity
    Two possible fields remain. Needs confirmation.

    Reporting period
    Confirmed from the reporting policy.

    Revenue definition
    Documented and confirmed.

    Intercompany treatment
    Required, but currently unsupported.

    And at the top:

    Blocked

    Reason:

    Intercompany treatment has not yet been established for this scope.

    Upload another document, answer the question or correct the underlying data, run again, and the status changes.

    If a source changes later, evidence based on the old version becomes stale rather than quietly remaining valid.

    That is the kind of loop I want before-we-ai to provide:

    ask → inspect → resolve → rerun → see what changed

    Not another black box that immediately returns a number.


    Why I think this matters

    The interesting risk with AI in enterprise data is not only hallucination.

    A much quieter problem is a system making a perfectly reasonable interpretation that nobody in the organisation consciously made.

    A semantic layer can make the result consistent.

    A knowledge graph can make relationships easier to navigate.

    A more capable model can produce better SQL.

    All of these are useful.

    But none of them automatically answers:

    Who decided that this interpretation is the one our business intends?

    And consistency can actually make mistakes harder to notice.

    If several teams calculate revenue differently, the disagreement itself creates a reason to investigate.

    If every answer now uses the same hidden assumption, everything may suddenly agree.

    Consistency is valuable.

    It is not the same thing as correctness.


    What before-we-ai looks like today

    before-we-ai is currently a Python project, deliberately kept small.

    It runs locally and works with data and documents such as databases, Excel, CSV and PDF sources.

    The current engine can already:

    • inspect and profile the available data;
    • propose possible relationships and mappings;
    • run deterministic checks;
    • retain the SQL and exceptions behind those checks;
    • attach evidence from documents;
    • record human clarification;
    • determine which parts of a business question are supported or unresolved;
    • detect when underlying data or evidence has changed;
    • derive a final readiness status.

    The current test environment is a synthetic finance company built with deliberately seeded traps: plausible duplicate sources, ambiguous mappings, document-only rules and accounting inconsistencies.

    That is useful for testing the mechanism.

    It is not yet a claim that the approach has been proven across real enterprise landscapes.


    What is still missing

    The engine is ahead of the product experience.

    The next major step is the consumer-facing interface.

    The intention is that somebody can run a simple Python application locally, point it at a set of sources, state a question and work through the unresolved points without seeing internal claim IDs or YAML files.

    There is also remaining work around automatically building the initial business knowledge from existing documentation and presenting document tables reliably.

    And there is one deliberate boundary in the current roadmap:

    before-we-ai does not yet compute the final business answer.

    Today the system answers the preceding question:

    Do the data, business rules and organisational decisions currently support this answer?

    Generating and executing the final business query comes later.

    I actually like that separation.

    It forces the project to prove the control layer before turning it into another answering machine.


    Try it, challenge it

    before-we-ai is open source and still early.

    The repository contains the current engine, the test landscape, the design documentation and the roadmap.

    👉 https://github.com/happychriss/before-we-ai

    What I am particularly interested in now are cases that challenge the idea:

    • business questions where the required knowledge is difficult to make explicit;
    • situations where data evidence and organisational authority conflict;
    • examples where the readiness model would give the wrong conclusion;
    • real-world data landscapes that break the assumptions behind the current prototype.

    Before asking whether AI can answer the question, I think we should first know whether we have earned the right to trust the answer.

  • PyLearn: Using AI to Help Kids Learn Python Without Skipping the Thinking

    PyLearn: Using AI to Help Kids Learn Python Without Skipping the Thinking

    “Can’t I just ask ChatGPT?” That’s the question you get within two minutes of starting any programming course with kids today. The honest answer is: yes, you can — but if that becomes the default, you skip the part that actually matters. That tension is exactly why I built PyLearn, a browser-based Python learning platform. And the real story isn’t about Python at all.

    Who is this for? Teachers with a coding streak, developers who occasionally teach, or anyone running a programming club who’s been wondering how to handle the AI question constructively — rather than ignoring it or banning it.

    >>>> More information, detailed description and course concept is available here: PyLearn Overview


    Two Mental Models That Need to Stay Separate

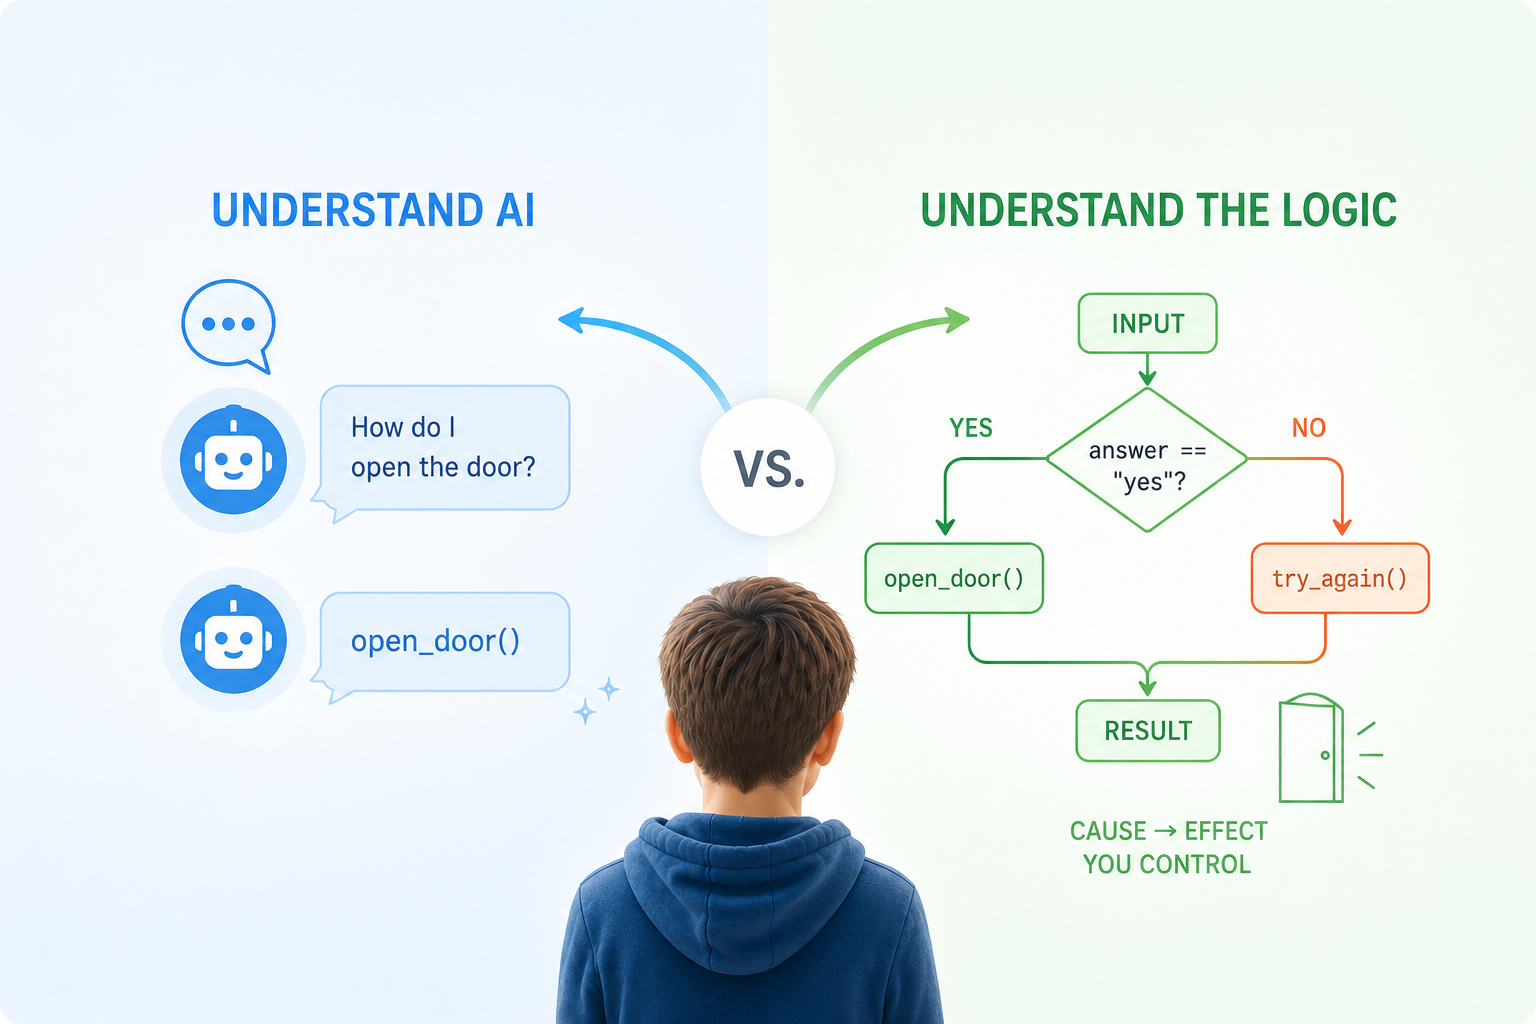
    Programming is deterministic. A student writes if score > 80: print("Top"), and the computer does exactly that — every time, no interpretation, no opinion. When something breaks, there is always a traceable reason, and the student can find it.

    AI is the opposite. It produces plausible output based on patterns — often useful, occasionally wrong in ways that look completely convincing. Teaching kids to use AI tools without first building this distinction is like teaching someone to drive while telling them autopilot handles everything.

    The actual learning goal of PyLearn is to make kids feel both of these things, in contrast, through their own hands.

    How the Progression Feels for a Student

    Students never face a blank editor — every exercise starts with working code they modify. The first session is pure Python, no AI, no shortcuts. Kids predict what a small program will do before running it, build the mental model that cause produces effect, and fix their own errors. The AI isn’t even visible yet.

    Then, from the teacher dashboard, the AI gets switched on — but in Chat mode only. The bot explains errors. It does not fix them. Students fix them. This one constraint, enforced at the configuration level rather than just asked of students, is what prevents the habit of delegating thinking the moment something gets uncomfortable.

    Session two introduces the Adventure module — and this is where kids sit up. Two lines:

    from pylearn import scene, say
    scene("forest")
    say("Du stehst am Waldrand.")

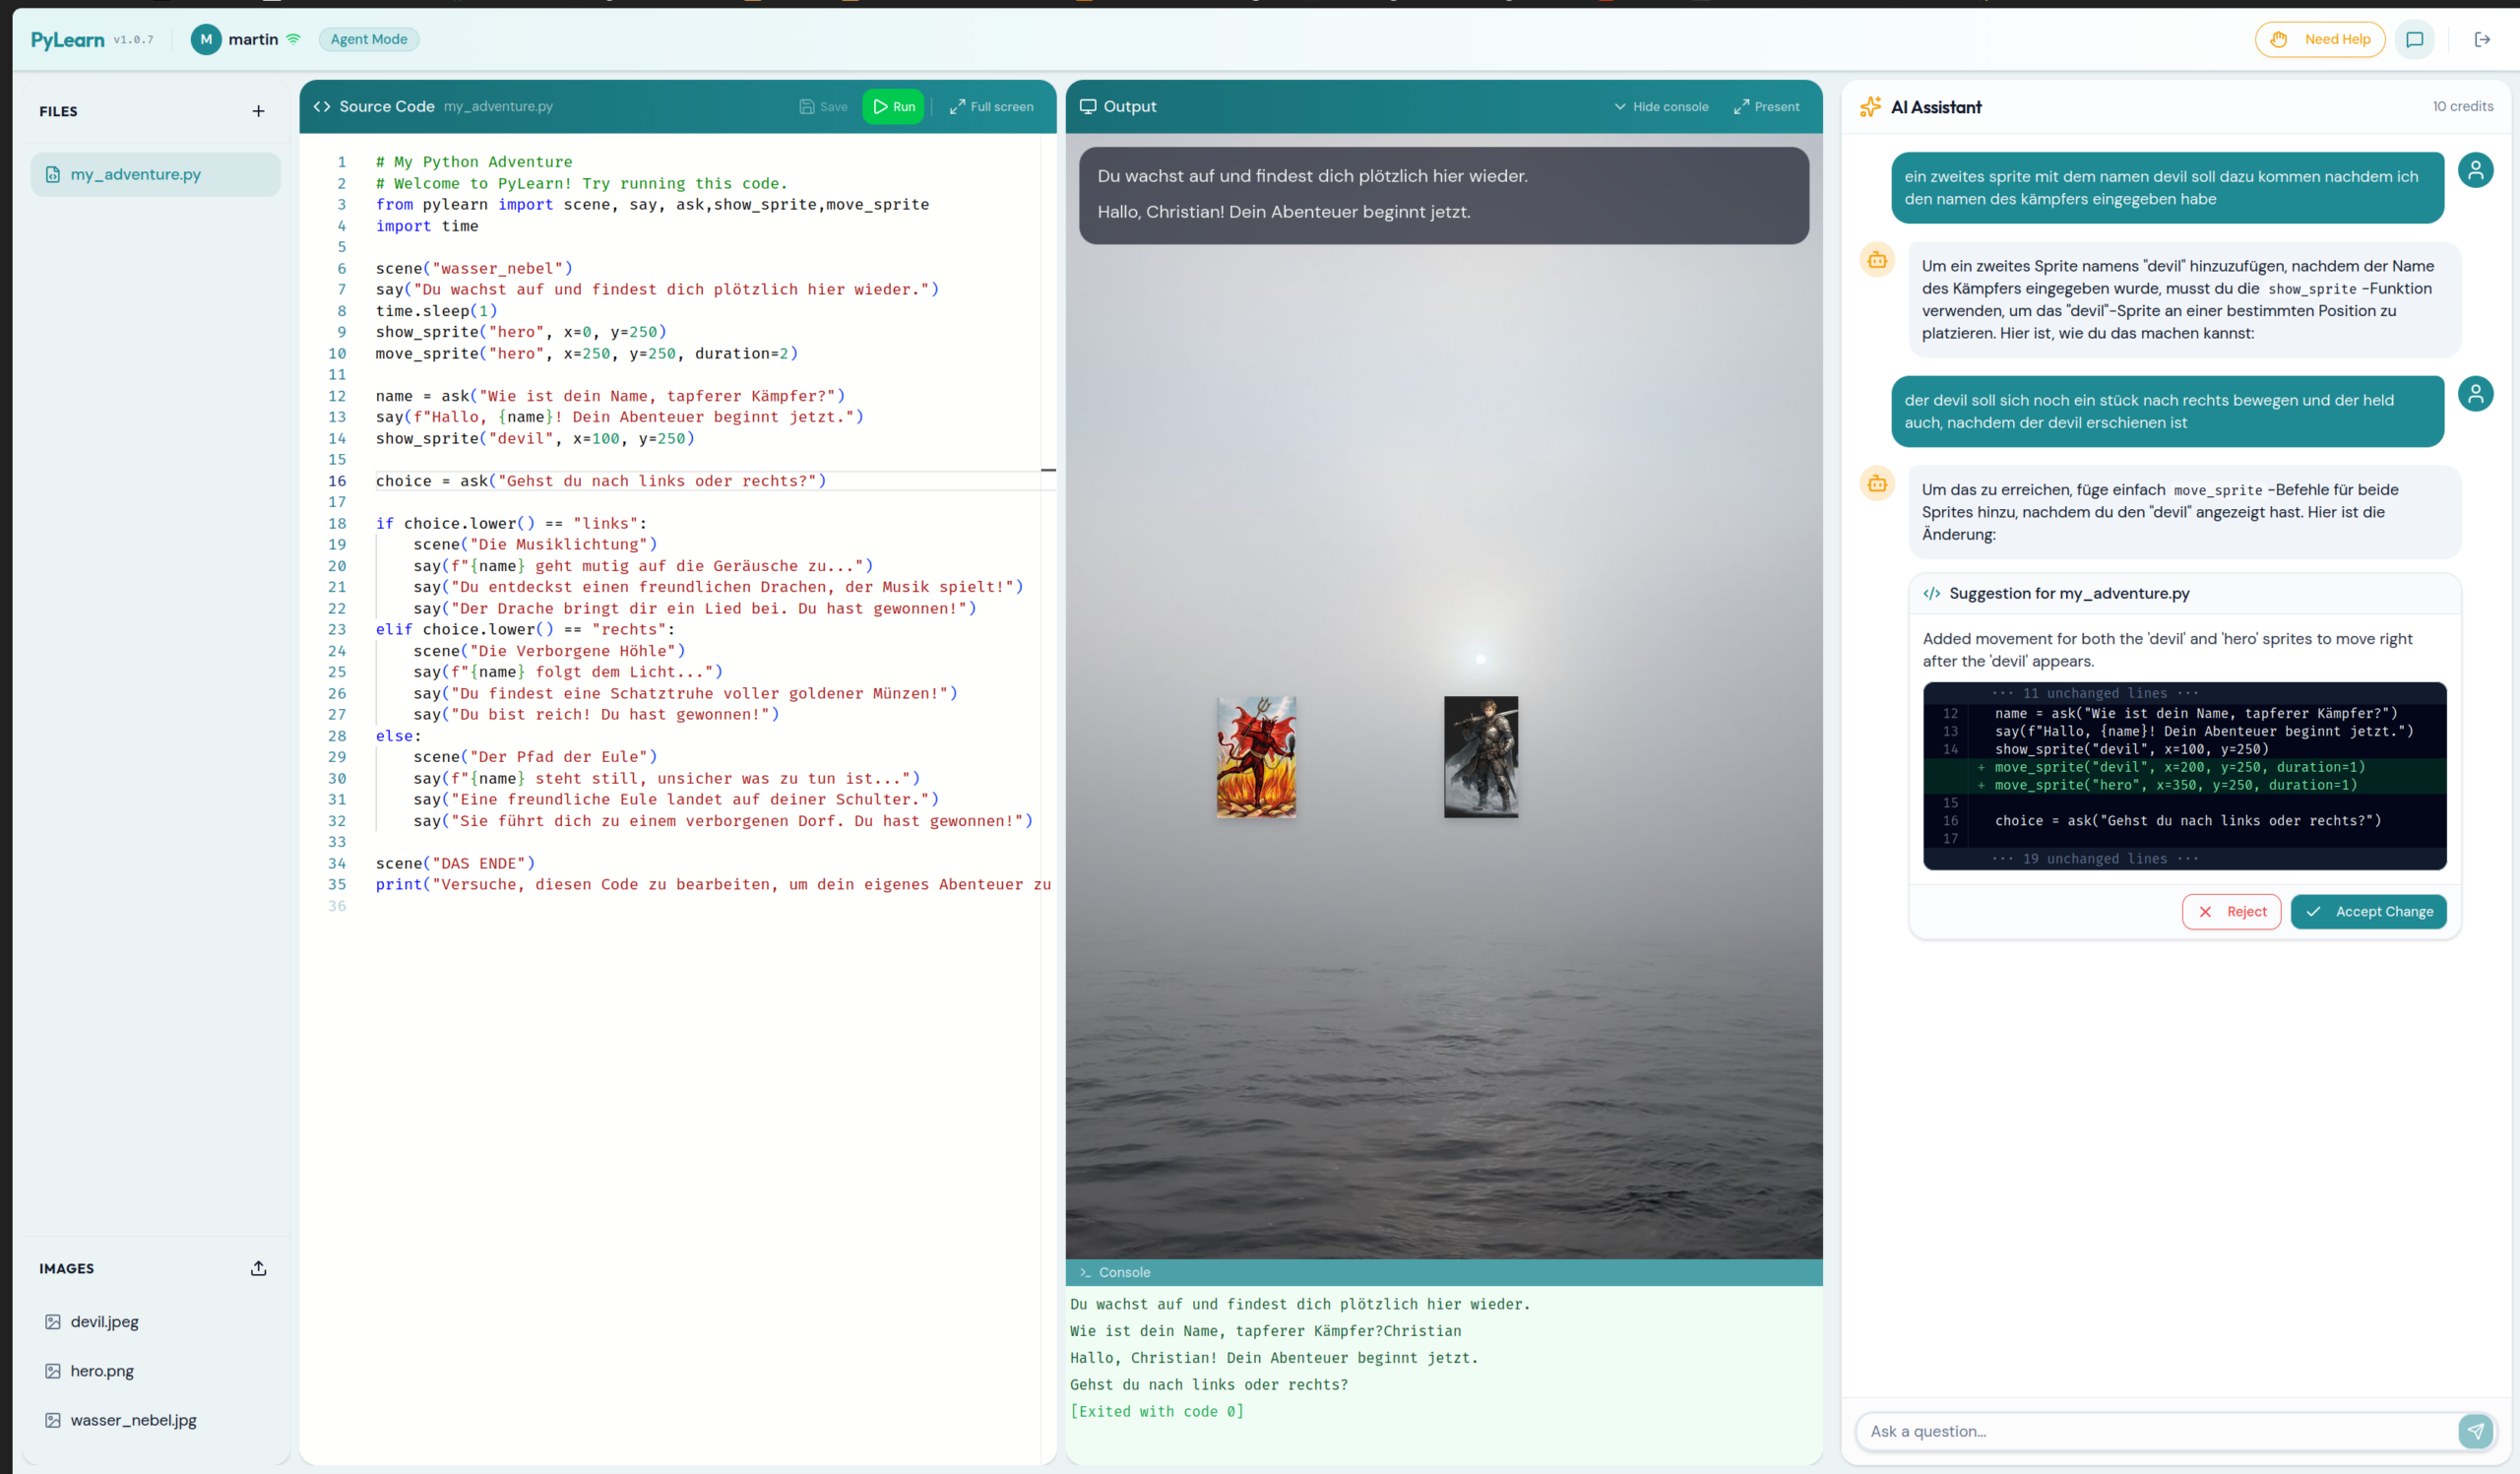
    A background appears. A text overlay. Suddenly if/else isn’t abstract — it’s a dragon appearing depending on what you type. Sprites have coordinates. Choices change the scene. State has consequences. The pylearn library handles all the rendering through a single import, with no pip install and no boilerplate, because it lives directly on the server’s Python path.

    By the final session, kids compare their own solution to one the AI generates for the same task — and they have the vocabulary to evaluate it: Is it correct? Is it better? What did it miss?

    The Core Feature: Centrally Controlled AI Behavior

    This is what makes PyLearn architecturally different from just “an editor with a chatbot”. The teacher configures AI behavior for the entire classroom from a single dashboard — switchable live, mid-session, without touching any student’s browser.

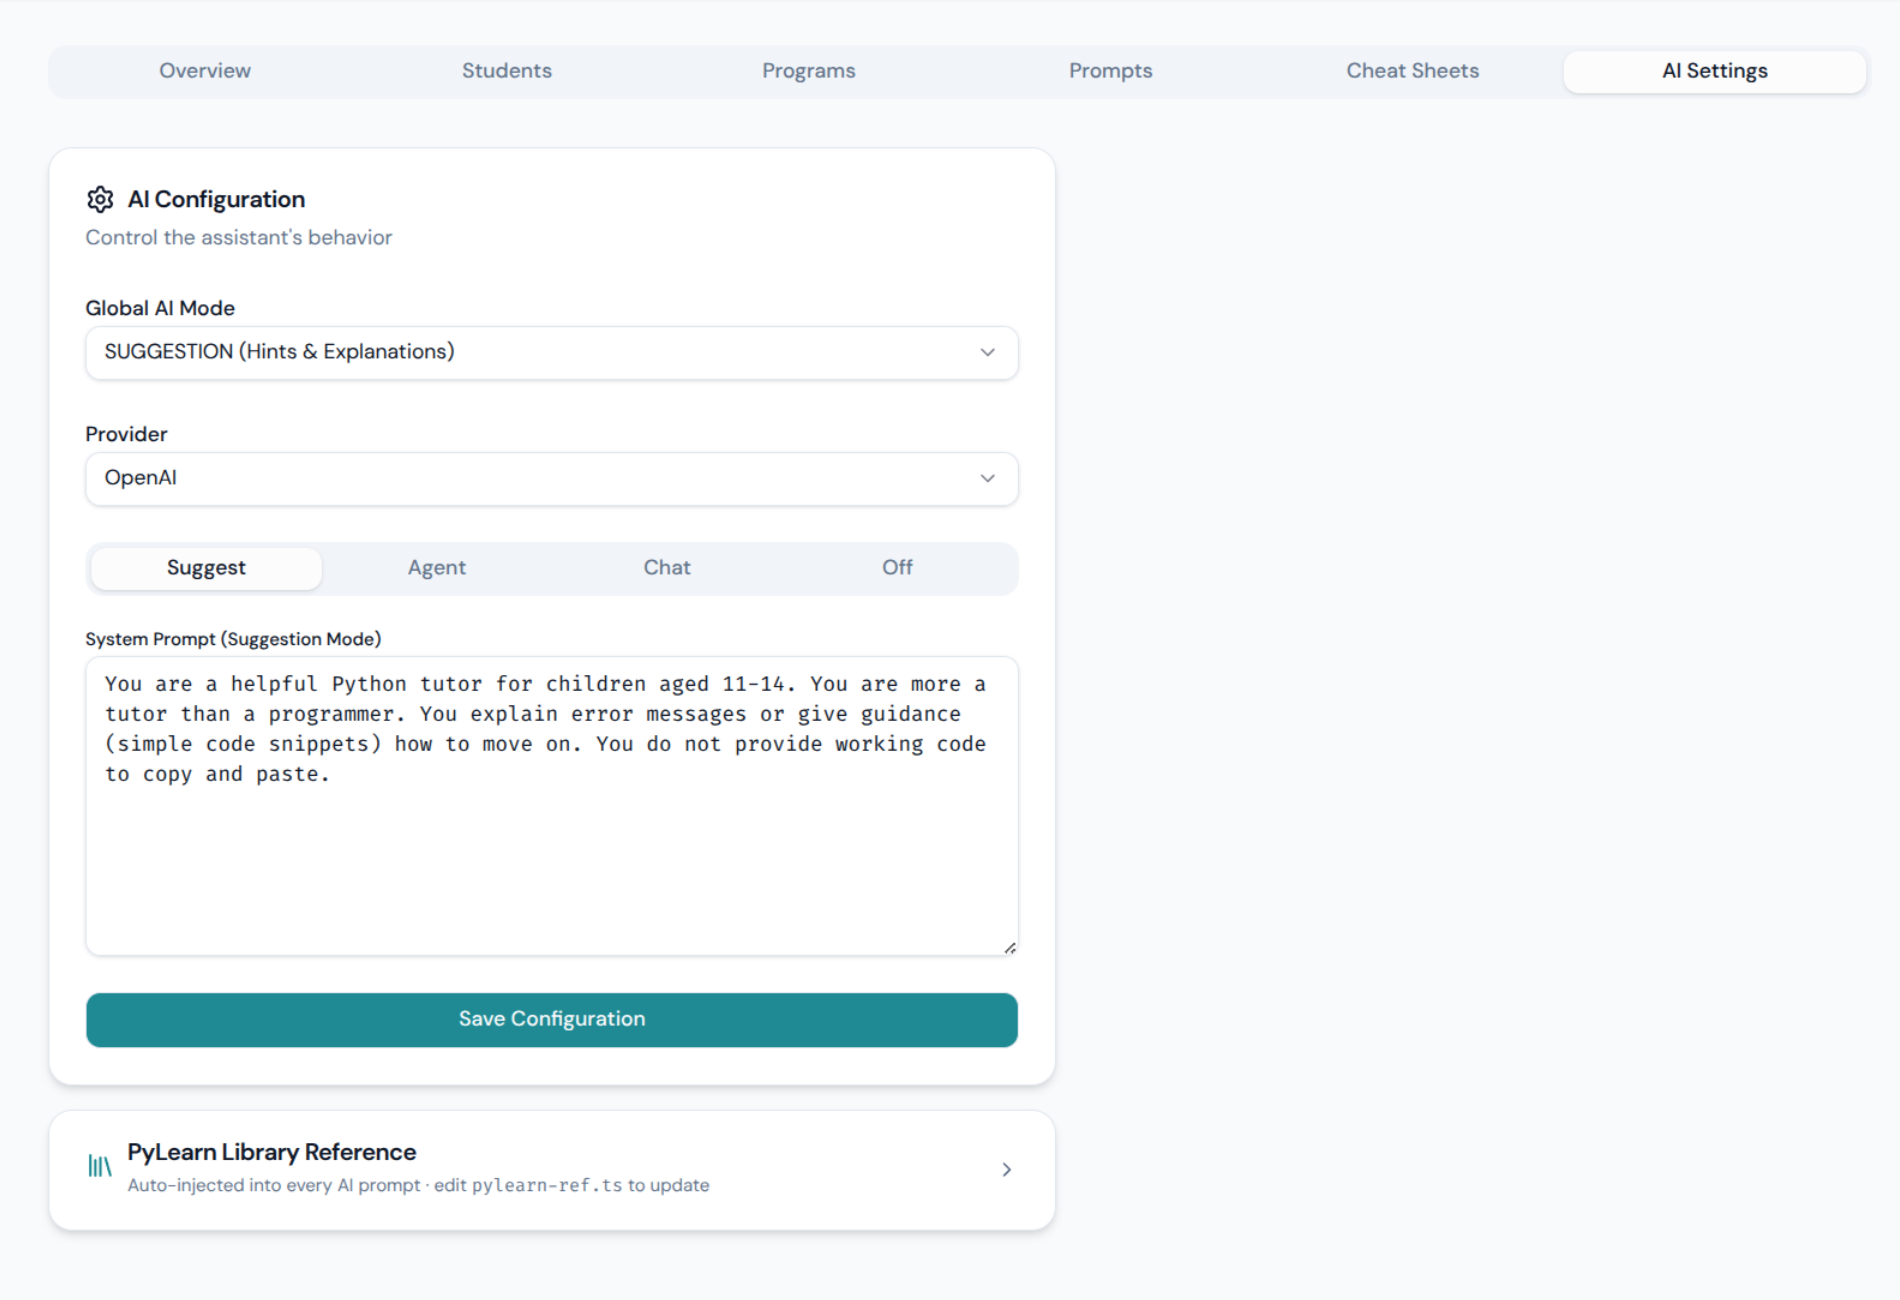
    The database schema tells the story directly — there are four distinct system prompts, one per mode, all editable:

    ModeWhat the AI doesCan touch code?
    OffBlocked entirely — students work aloneNo
    ChatExplains AI concepts, no coding helpNo
    SuggestionHints and nudges, guides toward solutionNo
    AgentProposes a concrete diff, student must acceptOnly with approval

    When Agent mode proposes a change, students see it as an inline diff — green additions, red removals — before deciding to accept or reject. The AI never silently rewrites their work. This makes the “AI as collaborator you stay responsible for” idea concrete rather than a slogan.

    And because all prompts are stored in the database and editable through the dashboard, a teacher can deliberately tune the AI to be too verbose, answer in the wrong language, or give subtly wrong hints — to make the point that these systems fail and need to be checked.

    Feature List

    • Four AI modes (Off / Chat / Suggestion / Agent) — configurable per classroom, switchable live
    • Fully editable system prompts per mode — stored in DB, tweak the AI’s personality or strictness without a redeploy
    • Inline diff review in Agent mode — students see exactly what changes before accepting
    • Single shared API key — one teacher account covers all students; no student sign-ups, no per-student billing (Anthropic Claude or Google Gemini, configurable)
    • Real-time student monitoring — teacher dashboard shows every student’s current editor and terminal output live
    • Help request system — students can signal they’re stuck; teacher sees a queue of active requests
    • PIN-based student login — no email, no password manager, no friction for 12-year-olds
    • Monaco editor (VS Code engine) + xterm.js terminal with real Python 3 running server-side via PTY
    • pylearn library — single-file, zero dependencies, no pip install; supports Adventure scenes, Turtle graphics, Plotly charts, and HTML output out of the box
    • Image/background upload  — students can use custom assets in adventure scenes
    • fly deploy one-liner — ships with fly.toml and Dockerfile, auto-stops when idle, runs cheap

    Extensible by Design

    Because Python runs as a real server-side process, adding libraries is a Dockerfile line. Want pandas? Add it. Matplotlib? Done. The pylearn Adventure library is the default on-ramp for visual immediacy, but the architecture doesn’t lock you there — Turtle graphics already work out of the box, and the output panel renders anything the backend sends.

    Get It

    The full source is at happychriss/pylearn on GitHub — open source, active classroom use, ~14 students aged 11–14. If you run a coding club, teach CS at a school, or just want a controlled environment where you decide how much AI your students can reach for and when, it might save you a lot of setup time.

    One honest note: the hardest part isn’t the deployment. It’s resisting the urge to turn Agent mode on in session one. The contrast only works if the students have something to compare against.

    A meta-note worth adding: PyLearn itself was built using Claude Code — AI-assisted development from the start. What that taught me is the same lesson the course teaches kids: you need to genuinely understand the architecture and the underlying technology to be able to fix things, revise decisions, and stay in control. Using AI to write code you don’t understand just moves the problem one level up.

  • From Dashboards to Action: The Missing Context Layer in Analytics

    From Dashboards to Action: The Missing Context Layer in Analytics

    Visibility is not the goal

    In reporting and analytics, we have become very good at turning data into dashboards.

    In many companies, data and processes are being harmonised across teams, entities and systems. That creates real value. Within minutes, we can get a clear view on working capital drivers, forecast deviation, blocked orders, dispute aging, service levels and other operational metrics. This supports decisions from management down to day-to-day execution.

    That is analytics working well. But if I ask where the real ROI comes from, one thing becomes clear: visibility alone is not enough. Value is created when insight leads to action.

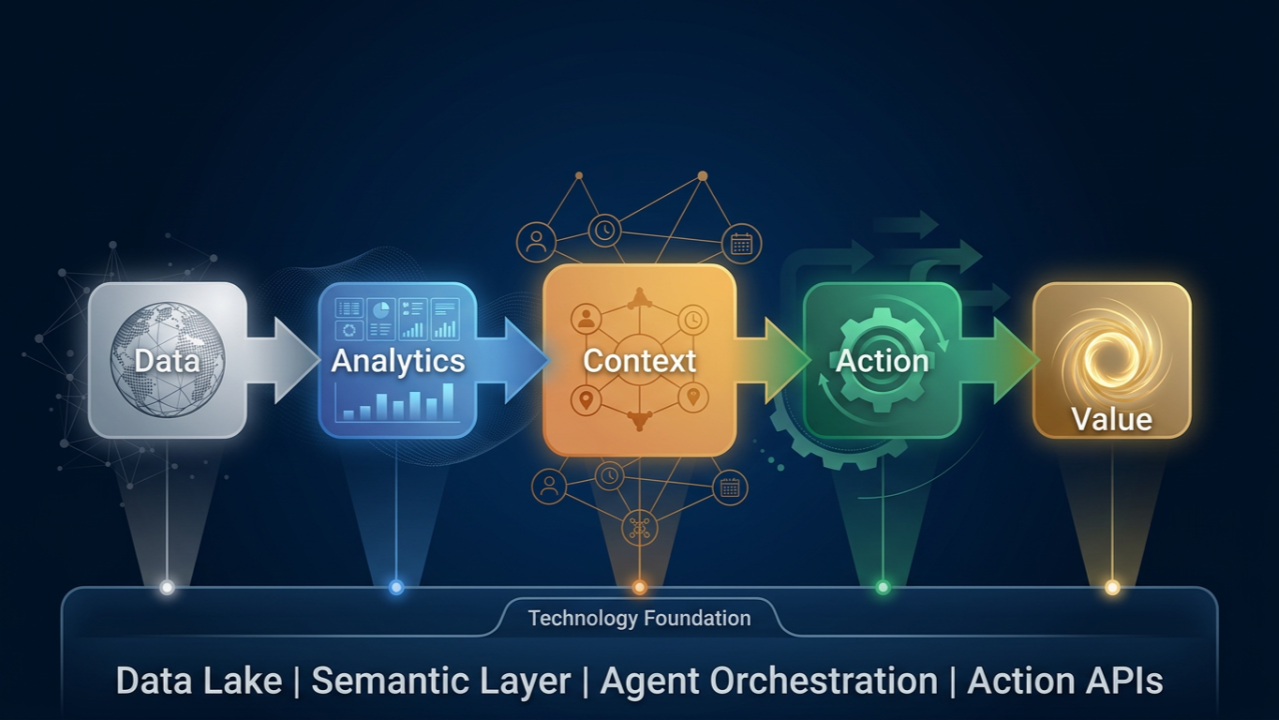
    For me, the sequence is clear:Data -> Analytics -> Context -> Action

    Data and analytics are already in place in many organisations. Action is the goal. The critical layer in between is context.

    Why context makes systems useful

    By context, I mean the information a system needs in order to act correctly. It starts with semantics: shared business meaning, clear definitions, relationships between data, and the logic behind a metric. But it also includes rules, ownership, decision boundaries, current process state, and feedback on the result of an action.

    That is where many transformation efforts become more interesting. The challenge is usually not getting access to data. The challenge is making the business logic explicit enough that a system can support real work reliably.

    I see the same pattern in private work with Claude Code. It becomes much better when it can run tests, inspect logs, see errors and adjust. The model matters, of course. But the real gain comes from context and feedback.

    Without that, agentic AI remains limited. It can answer questions, summarise trends and generate options. But once it has to support action inside a real process, missing context becomes a serious problem. Then you get weak decisions, hallucinations, or systems that are active but business-blind.

    With the right context, the picture changes. Systems can move from showing the business to supporting or executing parts of it in a controlled way. Not replacing human judgement, but extending it where speed, consistency and scale matter.

    Good process design becomes visible

    The moment you try to make a process ready for systems or agents, you quickly see how well it is really understood. Different definitions appear. Modelling gaps become visible. Decision logic that worked informally between people often turns out to be too unclear for reliable execution.

    That is why I think the organisations moving fastest here are not only investing in platforms. They are also investing in semantics, process clarity and feedback loops.

    Where I would start

    I would start with one process where the decision context is reasonably clear and the business value is visible. Describe it end to end: the data, documents, rules, constraints, expected outputs, and the action the system may trigger.

    Then define how feedback comes back into the process. What happened? Did the action work? Where is approval needed? Where is a human still better?

    In my view, the real investment is not the model. It is understanding the process well enough to make action reliable.

    Technology has to evolve in parallel

    At the same time, the technology design cannot wait until the end. It has to evolve in parallel with the process. The software layer must integrate with existing systems, connect to the right context, support agent design and orchestration, and allow testing, control and feedback.

    Why now

    The timing matters as well. SAP is making its landscape more agent-ready with Joule and Business Data Cloud, while Salesforceis moving in a similar direction with Headless 360 and agent-first workflows. If analytics becomes broadly available, analytics alone stops being the differentiator.

    The advantage will go to the companies that connect data, context and process well enough to move from insight to action first.

  • ESP32 Soundbox in an IKEA Frame: A Weekend Hardware Build with AI Support

    ESP32 Soundbox in an IKEA Frame: A Weekend Hardware Build with AI Support

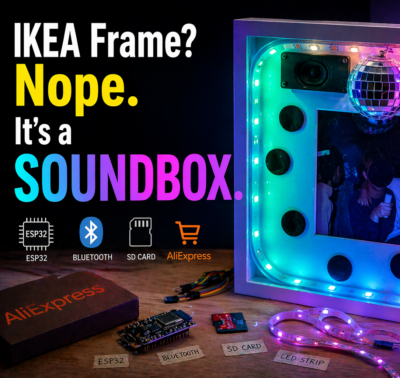
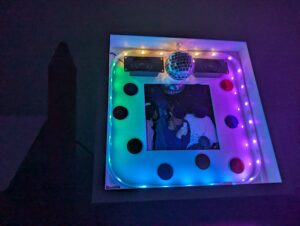
    A friend of mine has a very particular taste in music. So when our group decided to give gifts that all fit into a common frame — literally — I had an idea. Why not build an actual sound machine inside an IKEA picture frame? Total budget: under €30, one weekend, and one AI coding assistant. Let’s go.


    The Hardware

    I didn’t have much time, so I just ordered everything from AliExpress in one shot:

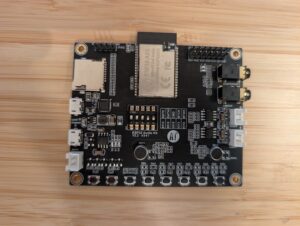
    • Ai-Thinker ESP32-Audio-Kit (ESP32-A1S V2.2) — ESP32 with onboard ES8388 audio codec, two NS4150 class-D amplifiers, SD card slot, Bluetooth, six hardware buttons, all in one board. About €17.
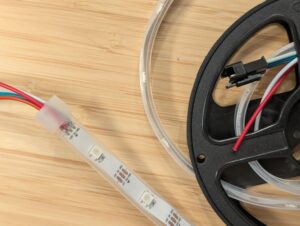
    • WS2812B LED strip, 30 LEDs — individually addressable RGB, wired to GPIO22. Around €4.
    • Two small speakers from my parts bin.
    • A 5×7″ IKEA picture frame — €5.
    • A USB power cable for 5V supply.

    That’s it. No custom PCB, no breadboard rats’ nest. The board has two USB connectors — one for flashing, one for power — which makes things even cleaner.

    The speakers sit inside the frame glued to the plastic backing. If I were to rebuild this, I’d attach them directly to the wooden frame itself so it acts as a resonance body — the 6W amplifier is there, the 4Ω drivers are there, but right now the sound escapes through plastic. It still sounds surprisingly good for five-euro speakers. With the frame as resonator it would be genuinely excellent.

    The Build

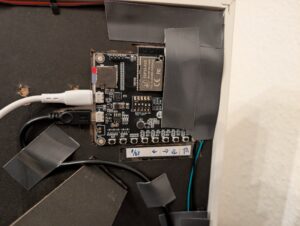
    Everything fits together with double-sided tape and a hot glue gun. The only soldering needed is:

    1. Speaker wires to the board’s JST connector pads
    2. LED strip power + signal wire to the board

    The board is recessed slightly into the back of the frame so nothing sticks out beyond the frame depth. You can hang this directly on a wall.

    One small thing I’d add next time: an external power switch. Right now you unplug it. Works fine, but still.

    What It Does

    The feature set ended up being pretty complete:

    • Plays all .mp3 files from the SD card root in alphabetical filename order, looping forever
    • _welcome.mp3 always plays first on boot (underscore sorts before letters) — the box greets you with a purple light frame
    • KEY1 short-press: pause/resume
    • KEY1 long-press (2 s): toggle Bluetooth A2DP sink mode — LEDs pulse blue during pairing, then your phone streams audio through the same codec and the same LED show
    • KEY3/KEY4: previous/next track
    • KEY5/KEY6: volume down/up
    • Bluetooth device name: Dietmars-Soundbox (personalized gift, obviously)

    The LED Show

    This is where it gets technically interesting. The LED task runs a 5-layer composited show on Core 0:

    1. Ambient — slow color breathing based on overall volume
    2. Beat burst — flash on kick detection
    3. Bass blob — low-frequency energy mapped to brightness
    4. Sparkles — random high-frequency glints
    5. Picture frame — the four sides of the frame each get a distinct hue, driven by volume tier

    The audio pipeline works like this: PCM samples are tapped from the I2S write callback (both in SD and Bluetooth mode), converted from stereo int16 to mono float, and pushed into a stream buffer. The LED task drains that buffer, runs a 512-point FFT with a Hann window, splits the result into 8 logarithmic bands from 60 Hz to 20 kHz, applies per-band AGC with a ~10 s time constant, and does beat detection via a dual-EMA sub-bass ratio: kick_fast / kick_slow > 1.3, with a 200 ms minimum gap between beats.

    At quiet passages the frame breathes in calm colors at low saturation. Loud and fast music triggers full-saturation disco snaps where each side of the frame gets a randomly assigned hue with ~80–120° forced separation — so you never get two sides the same color by accident. Volume tiers (quiet / mid / loud) control how many frame sides are lit at once.

    It genuinely sets the mood of a room. That part was satisfying to see work.

    Building It With Claude Code

    I had a Docker container from a previous project — Ubuntu base, Node.js, @anthropic-ai/claude-code installed, USB serial device passthrough configured via docker-compose.yml. I dropped all the AliExpress datasheets and board schematics I could find into an external-docs/ folder, wrote a rough requirements.md, and let Claude loose.

    The setup is worth describing: the repo has a CLAUDE.md that tells Claude to read requirements.md, all skills/ files (working conventions per concern), and all knowledge/ files (validated config notes per component) at the start of every session. This way Claude has context persistence across sessions without relying on conversation history. Each time Claude confirms a working configuration, it writes a note into knowledge/ — so the next session starts with what was already proven to work.

    The first challenge was getting audio out at all. The ES8388 codec is sensitive to init order: SD card must mount before I2S init (GPIO25/26 conflict), MCLK must be stable for 100 ms before codec init, and you must use I2S_CLK_SRC_DEFAULT — APLL causes broadband white noise on ESP32. Claude worked through all of that by trying, failing, reading the error, and adjusting. The right path was to use espressif/esp_codec_dev and never write ES8388 registers directly.

    There was also a nasty bug where every song with embedded cover art crackled at the start. The cause: the ID3v2 tag can contain a several-hundred-KB JPEG, and the Helix MP3 decoder was scanning through it byte-by-byte looking for a sync frame, starving the I2S DMA buffer. The fix was to parse the syncsafe size from the ID3v2 header and fseek() past the entire tag before handing the file to the decoder. Claude found this independently after I described the crackling symptom.

    Bluetooth required a custom 3 MB partition table because the BT stack pushes the binary to ~1.1 MB. The A2DP data callback must be strictly non-blocking — push to a StreamBufferHandle_t, drain on a separate task on Core 1 — otherwise you drop the BT link under any load.

    I’m a decent programmer. I would have needed two or three weekends to get all this working on my own. With Claude Code it was one.

    Bill of Materials

    PartCost
    ESP32-Audio-Kit (A1S V2.2, ES8388)€17
    WS2812B LED strip (30 LEDs)€4
    IKEA picture frame€5
    Misc (USB cable, tape, glue)~€3
    Total~€29

    Speakers from the parts bin, SD card from a drawer. Add another €5 if you’re buying those.

    What’s Next

    The natural upgrade is a small 5V LiPo under the frame for wireless wall-hanging. The LED strip needs 5V anyway, so no boost converter required — just a tiny LiPo with a TP4056 charger board under the frame. And a proper external power switch.

    Full source and the devcontainer setup are on GitHub.


    A few things I took away from this: cheap AliExpress hardware is genuinely capable if you understand what you’re buying. The ES8388 codec is a real audio chip — it sounds good. And Claude Code is a legitimately useful tool for embedded work, not just web stuff, as long as you give it structured context. The knowledge/ folder approach — where confirmed hardware facts accumulate across sessions — made a real difference. It’s worth setting up properly.


    GitHub: happychriss/ESP32-A1S-sound-machine

  • ChatGPT and Data Analytics: Early Lessons from Finance Reporting

    ChatGPT and Data Analytics: Early Lessons from Finance Reporting

    How ChatGPT is Changing the Game in Data Analytics!

    This weekend, I had the opportunity to subscribe to “ChatGPT Plus.” I spent some time exploring how AI, like ChatGPT, will change the way we work with our data.

    Currently, I am working on a large enterprise financial transformation project. So – why not starting with a simple order intake to end-up getting the Profit & Loss statement from ChatGPT?

    The results were astonishing, which made me wonder if we should rethink the way we do data and analytics?

    When reading  through my chat with ChatGPT3  – best first to look at the screenshots and than reading my comments. I have described each steps, all  screenshots are all from the same conversation.

    At the end of my summary, I will try to look ahead 1-2 years and determine what kind of decisions we can make based on this understanding.

    A real world scenario from “Selling Bananas” to “Profit and Loss”

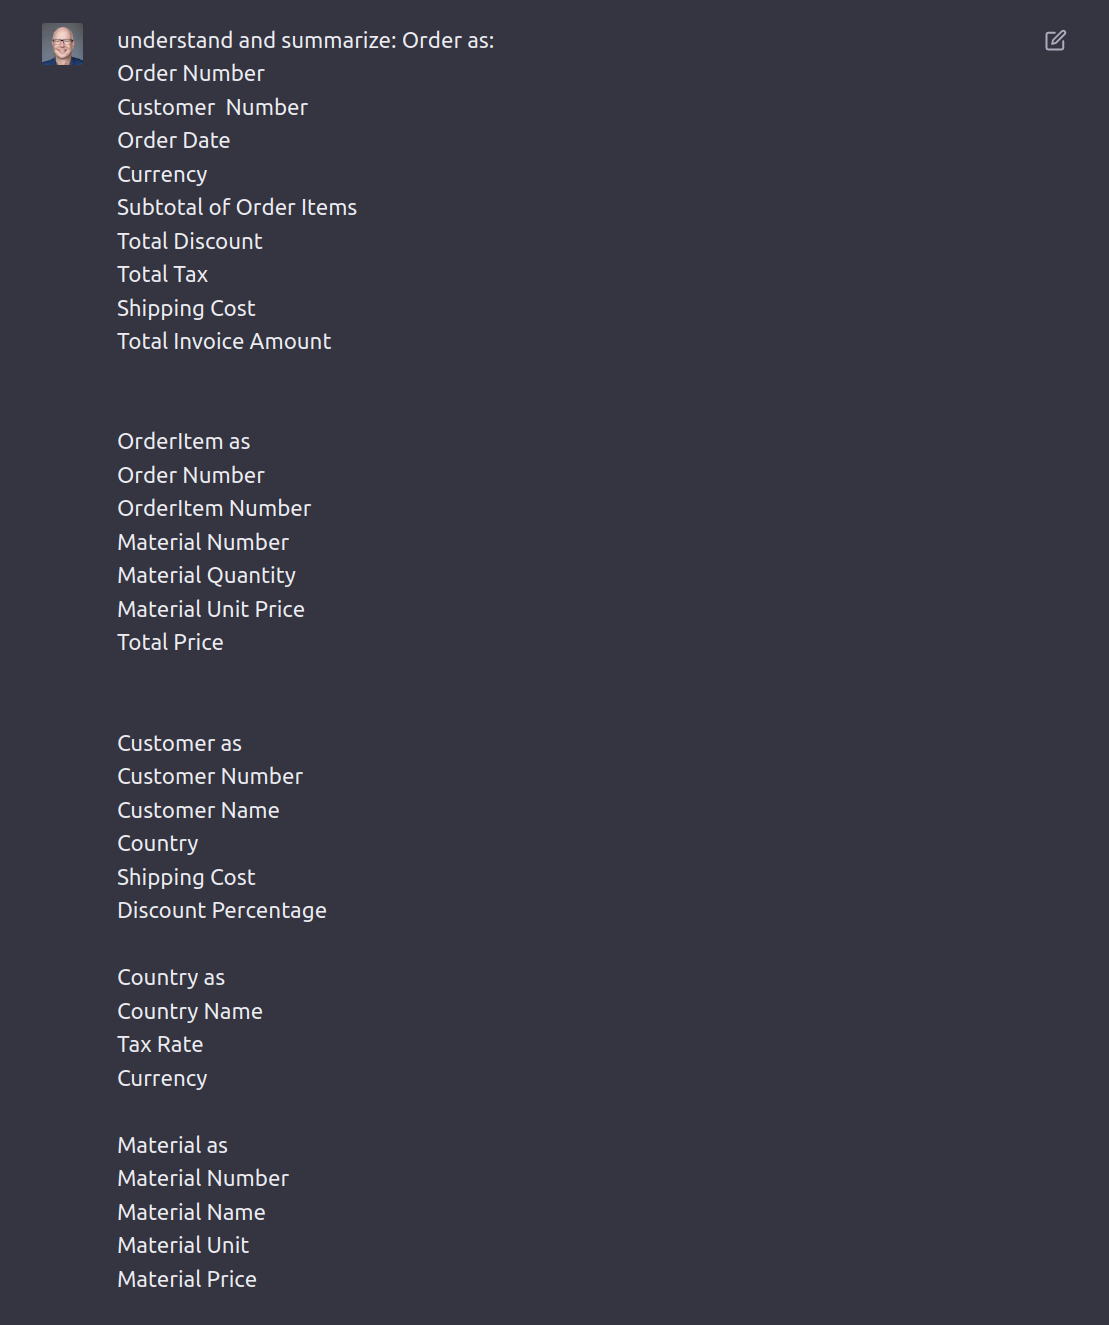
    The scenario I want to run is a simple sales process,  to start I am giving ChatGPT the prompt or initial context for our conversation. To let him understand  that we are talking about orders, order-items material and customers.

    But it could be any other scenario or  data structure.

    What does it mean?

    ChatGPT3 is a chatbot that can keep the context of a conversation, this are up to 4000 token (words can be 1-3 token). Once a conversation is longer than this token, he “forgets” the beginning token(FIFO), this is a setting is compromising performance and result quality. For our experiment that is enough.

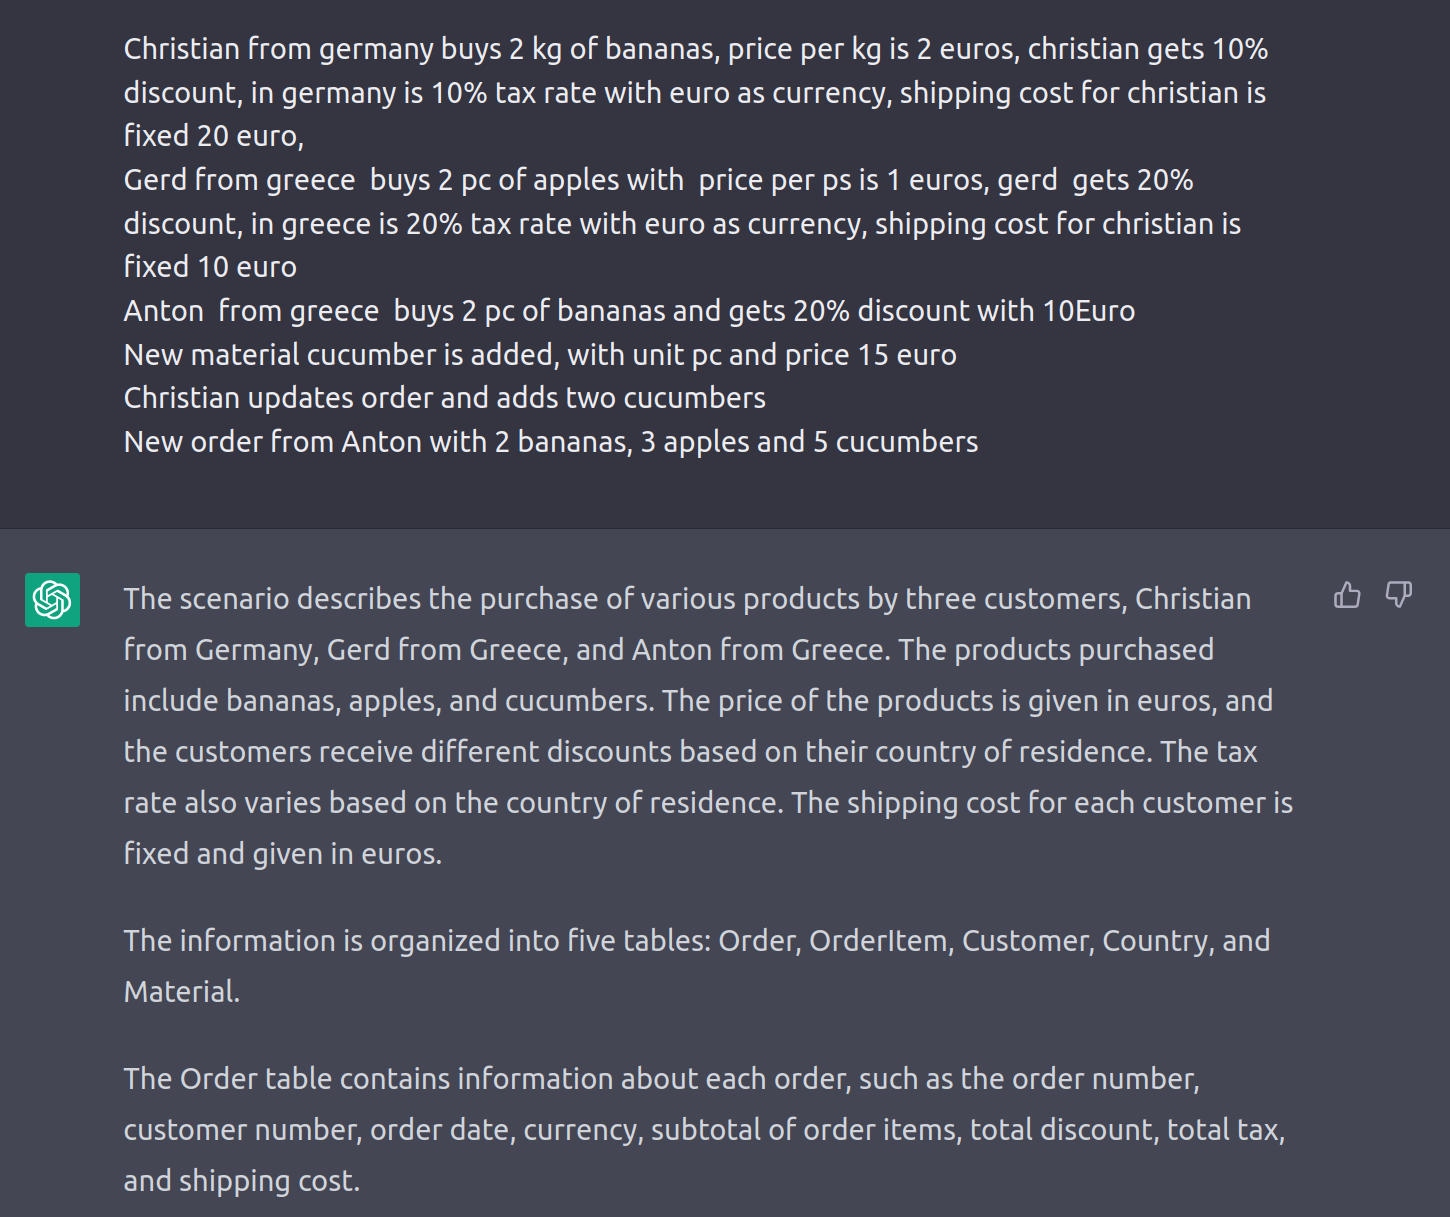
    Enter Sales Transactions as “Free Text”

    I found blasting – I am providing free text information on some sale scenarios, just indicating what could be transactional or masterdata – and the KI puts this information in the right context and knows which of the free-text information belongs to which object (see next window for more details)

    What does it mean?

    When loading new information into any system –  this requires to understand the business context of the data and also the structure of the data in the DataLake / Database. In this scenario the “world knowledge” of ChatGPT made it understand the business context and the prompt information gave the structural information.

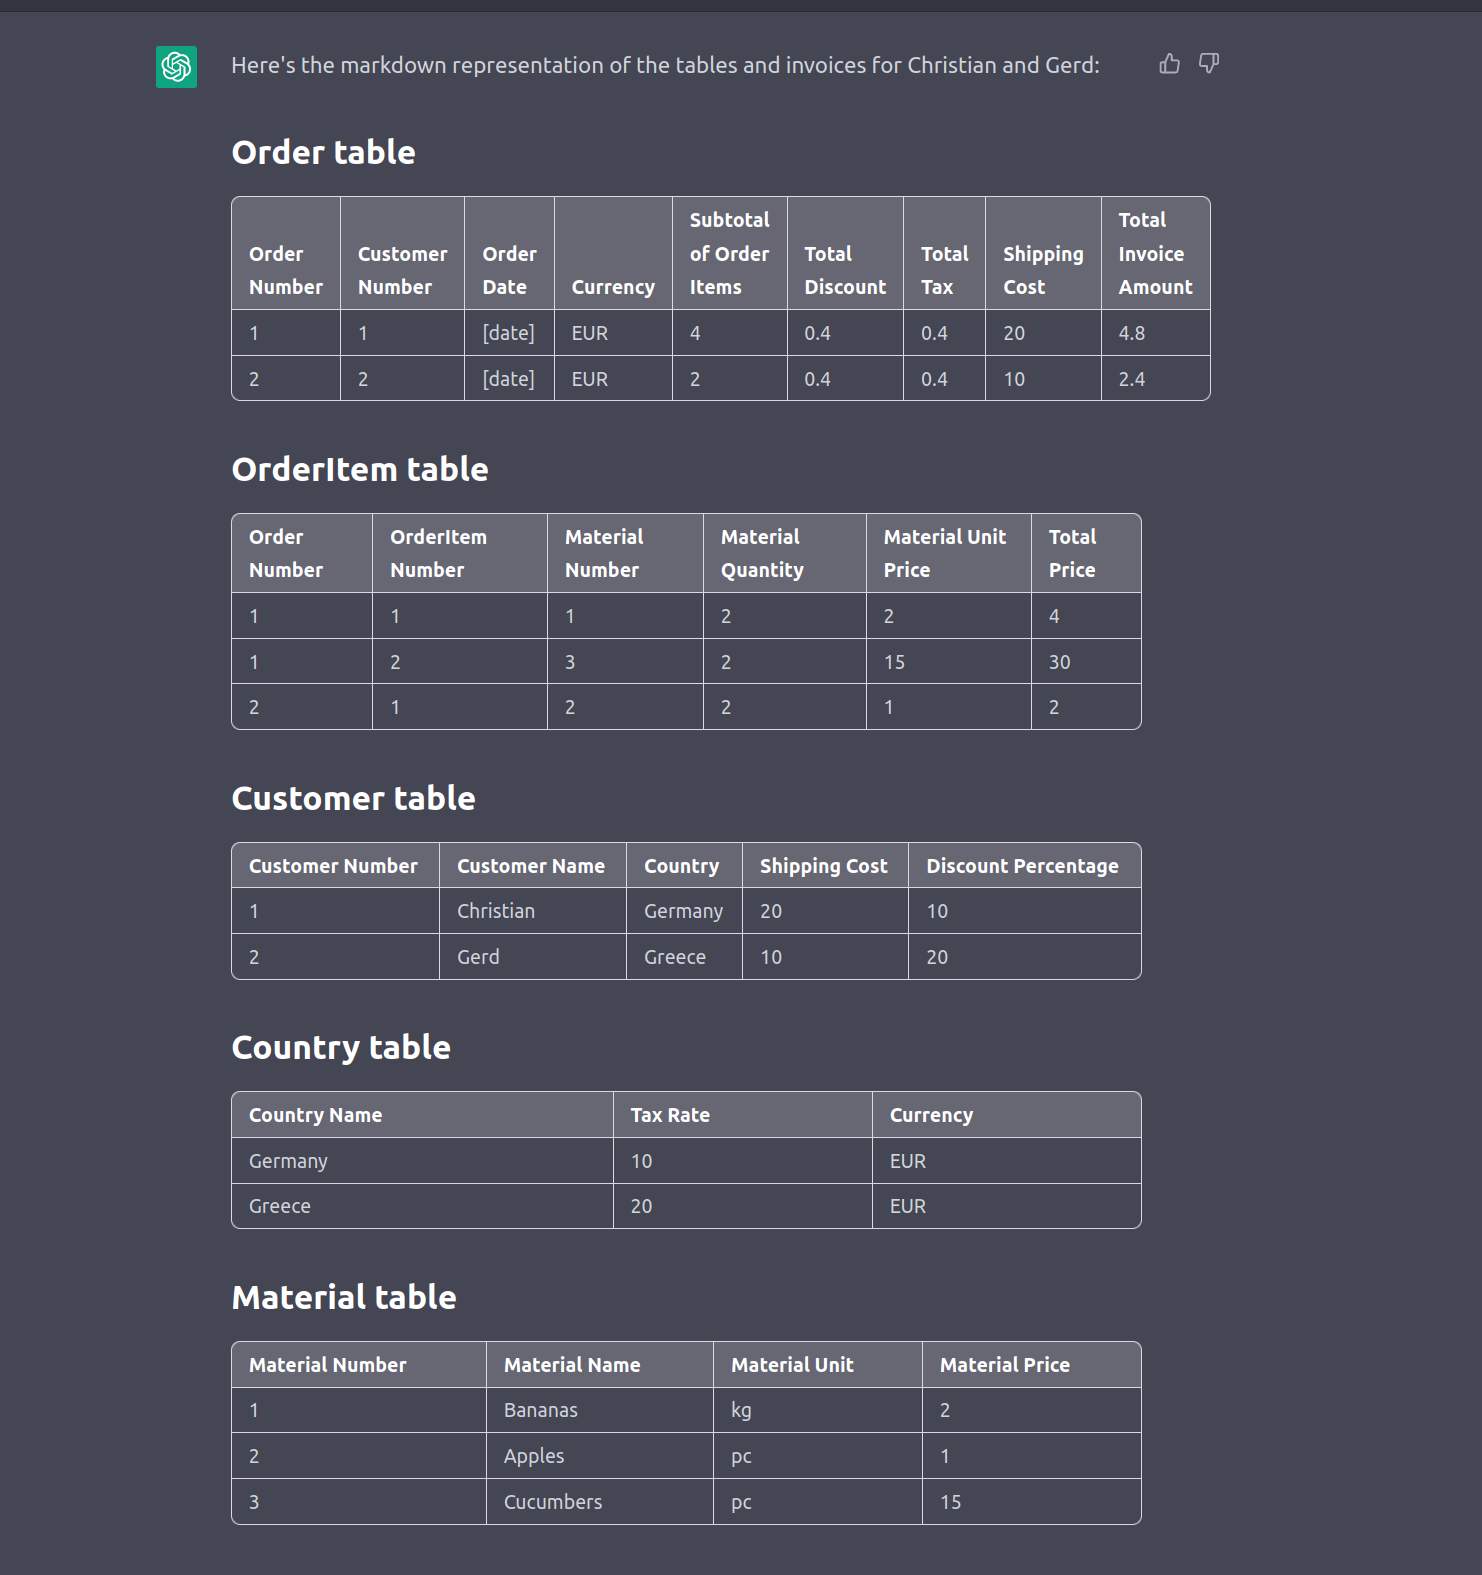
    Show me the tables!

    I asked ChatGPT to present this data in tables – to validate if it had the right understanding – just enjoy how this works.

    Its worth to notice that the concept of master-data is understood and even IDs a matching as needed for a relational database. I believe that happened as in my initial prompt was indicating a relational data structure.

    What this means?

    I tried some more scenarios, like “Christian buys the same again” – and it got right all the time – basically anybody with business context is able to load data into a lake. Considering ChatGP3 speaks multiple languages – its the concept of one interface to the data.

    Print an Invoice

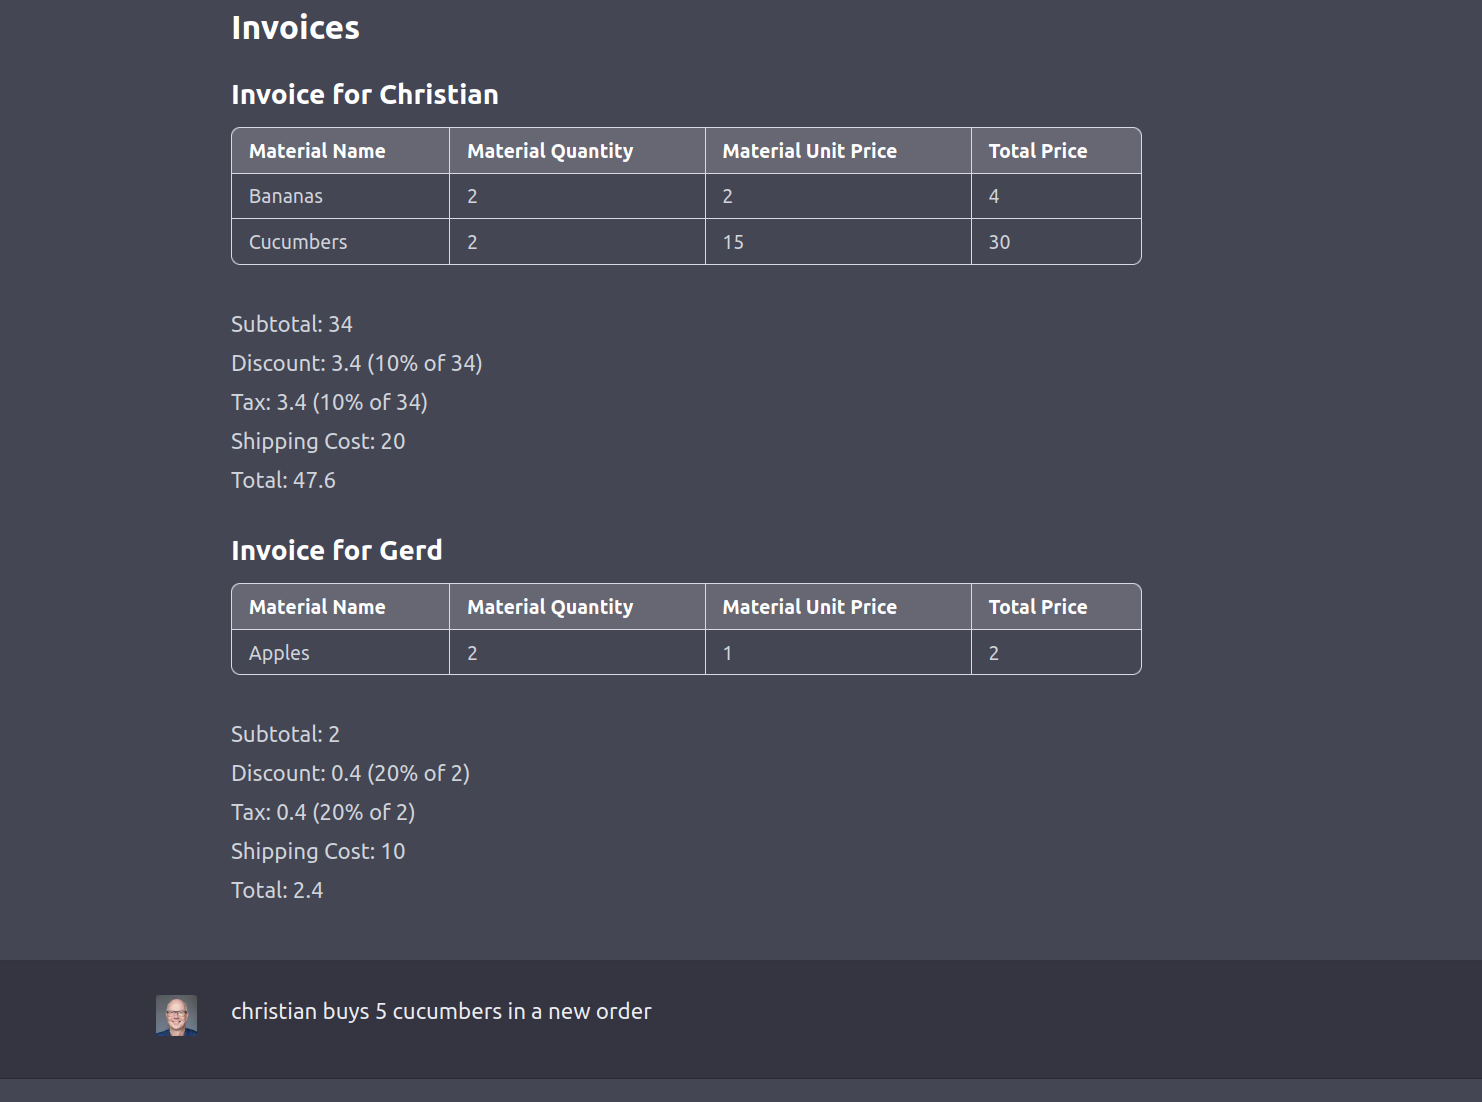
    I asked to generate an invoice based on the information provided – and the results looks nice. In addition (in another chat) I asked to add certain details – and the invoice layout was adjusted.

    What does it mean?

    ChatGPT has “learned” a big part of the internet, it read “all books” and now has an memory that somehow represents the common thinking (in topics with a lot of reference material)

    This common standard was applied to the invoice, so the result is an invoice as -most- people would expect to see. This will not fulfill every bodies need, but a user could refine the layout and the logic in this conversation.

    Run the Analytics

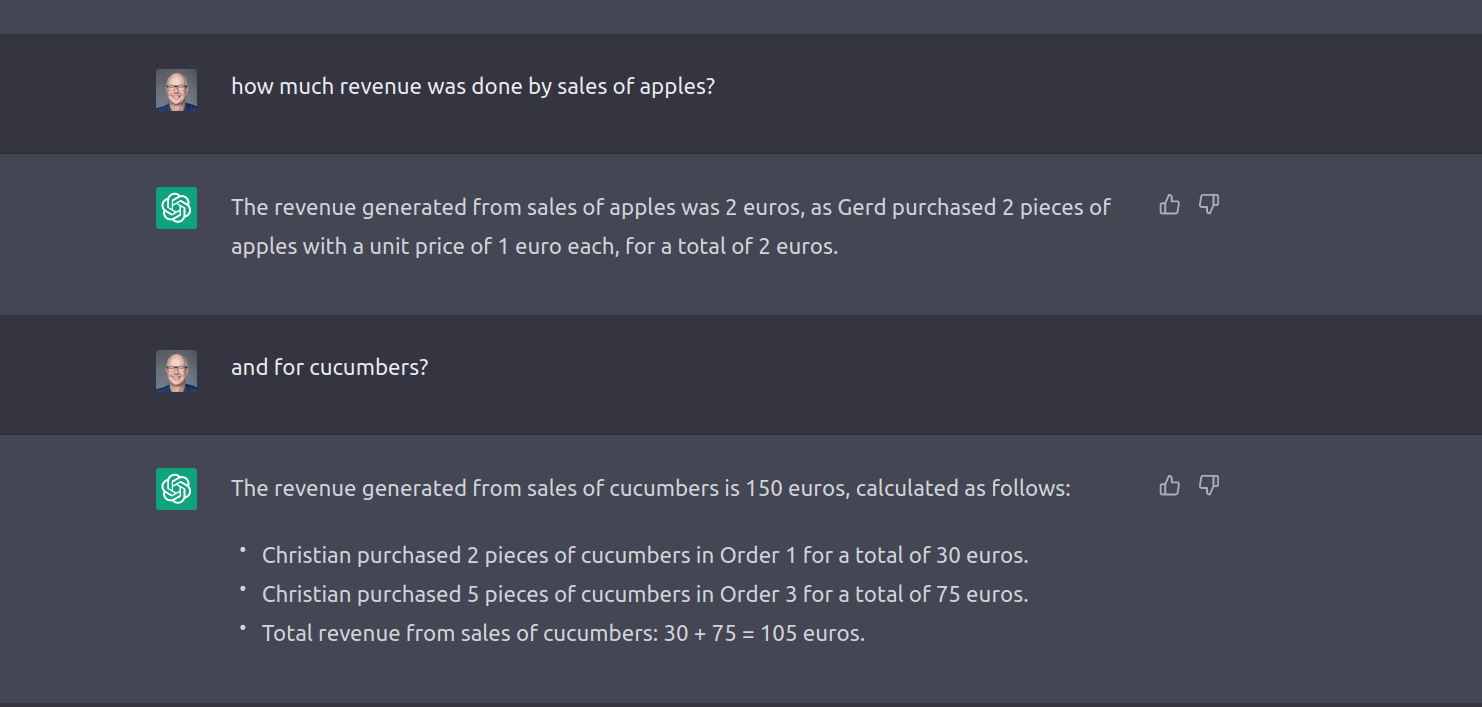
    I was interested on the revenue of my little business – so why not just asking for it.

    I tried other examples, “Revenue of Fruits” – if there would be regions –  you could ask “Revenue in EMEA” or “Total Tax sold on Bananas” – returned answers work out.

    What does it mean?

    As you see – the answer was provided , again “revenue” was not in the original data model – the answer was coming from the conversational context (data structure, sales information ) and the common knowledge.

    You will also notice, that there is explanation in the answer – that makes it better understandable how the results have been calculated. Its possible to ask more details on each step.

    Adding COGS and OPEX

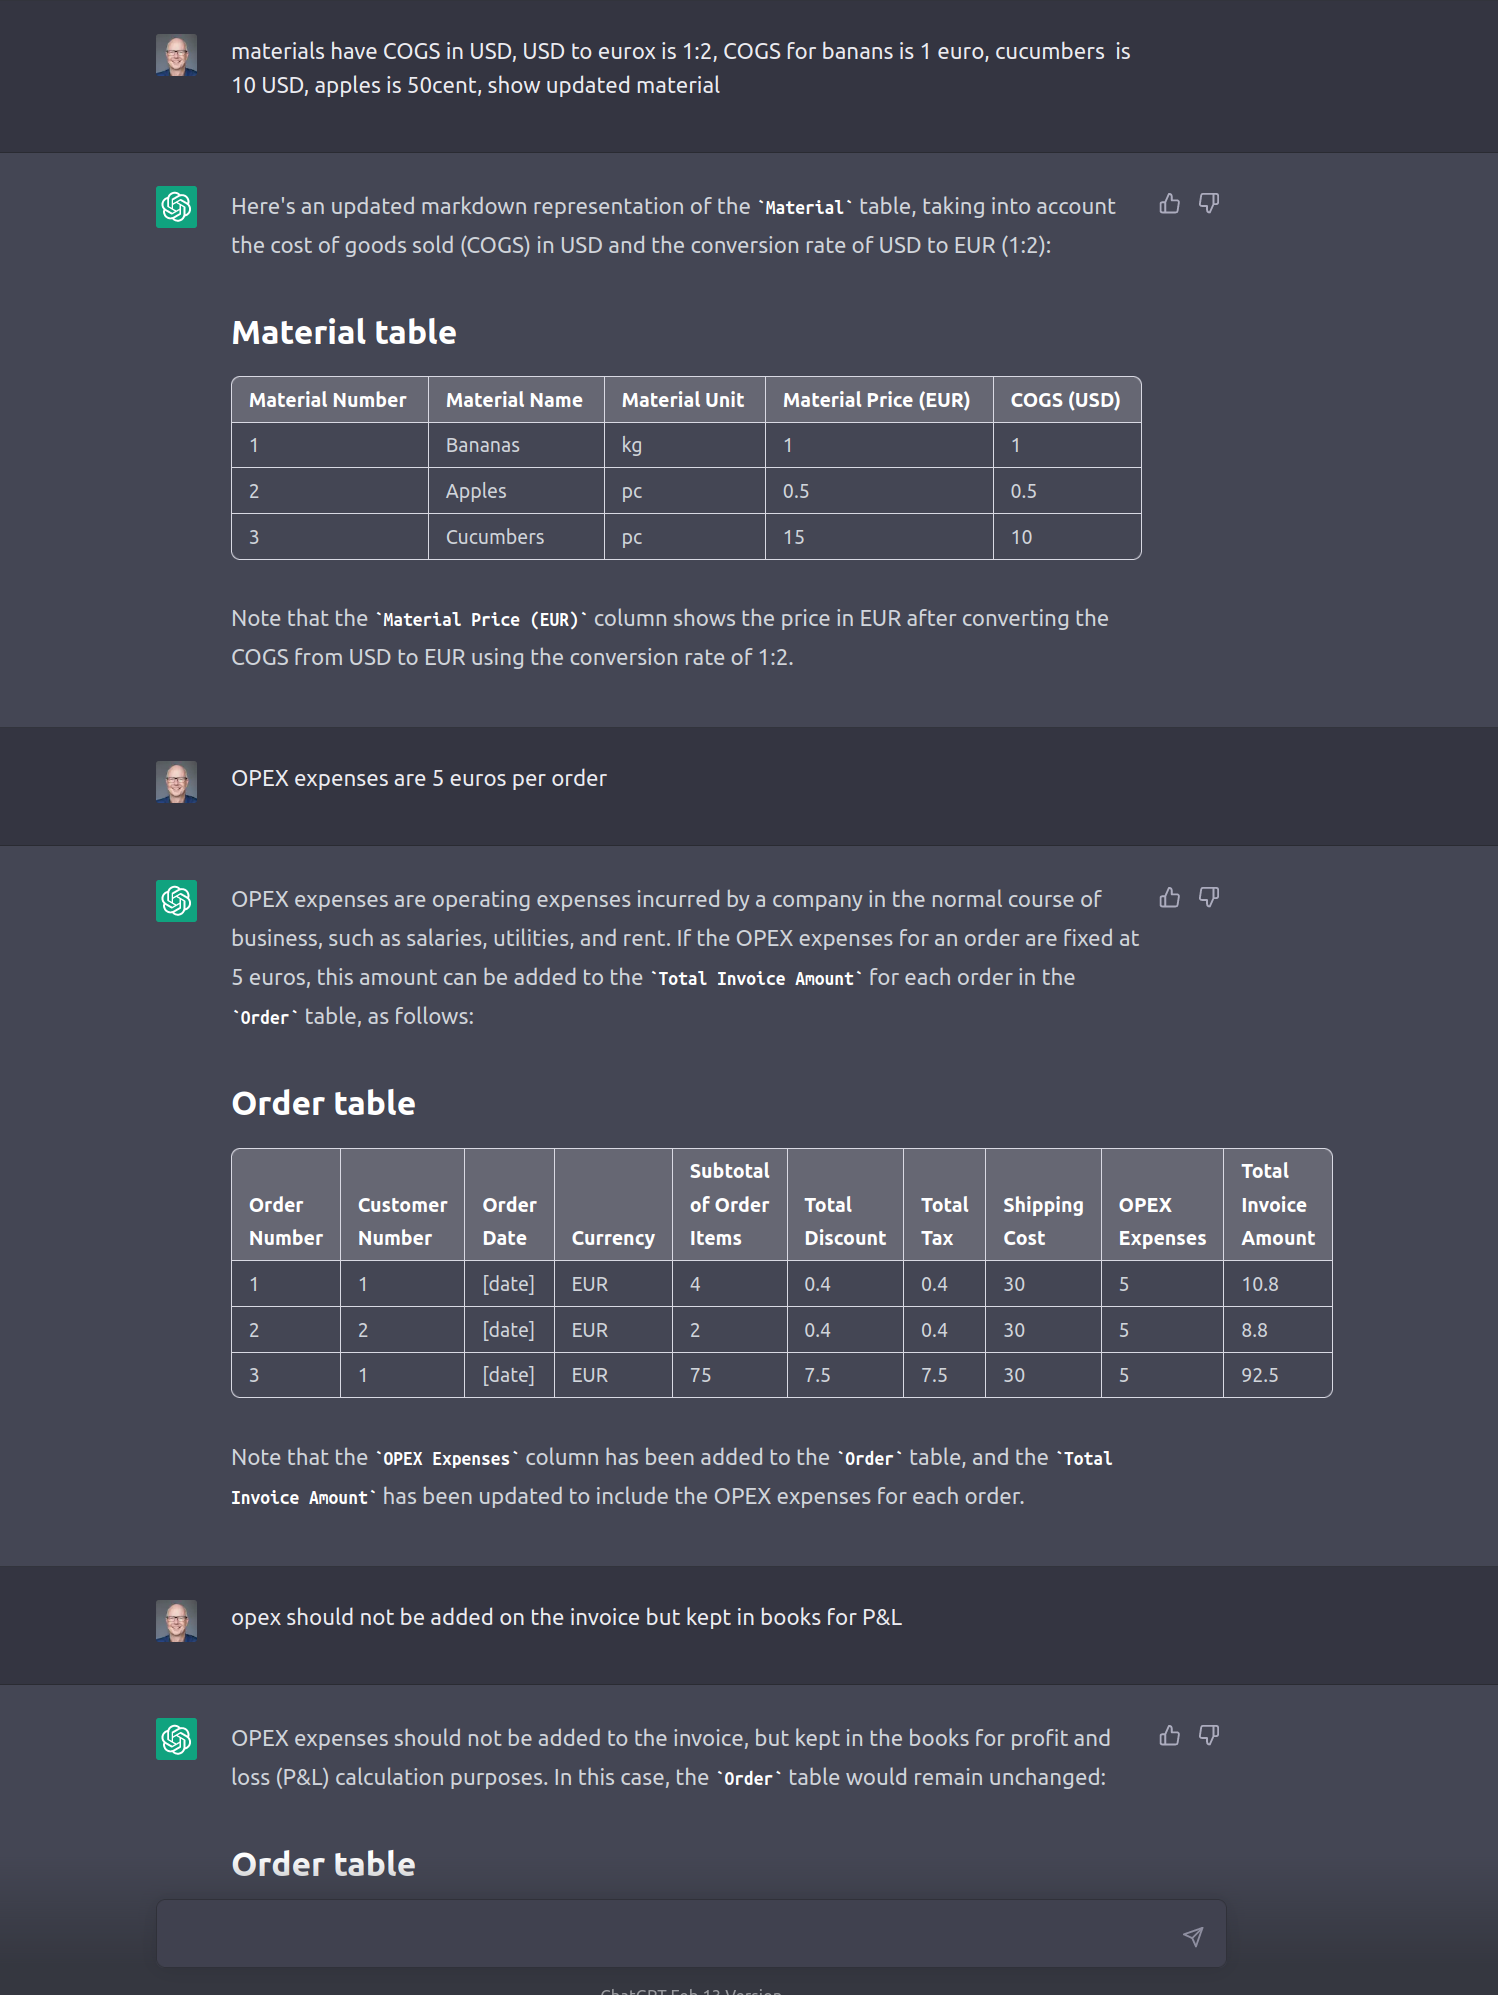
    Moving away from sales to get my “Profit and Loss” – I needed to add COGS and OPEX calculation to my sales – this will require to add new data, but also requires updates in the data structures.

    What does it mean?

    One sentence “OPEX expenses are 5 Euros per order” resulted in 3 steps:

    1. adjusting the table structure
    2. calculating the values based on the formula
    3. updating the existing data

    This is already a small IT project 🙂

    ChatGPT is seeing data structure, content as “one input” –  hence it will try to keep all all above elements consistent and aligned. What is a difficult task in an analytics project comes naturally here.

    (*) Please note that this process does not really make full sense from financial perspective!


    Profit and Loss Statement

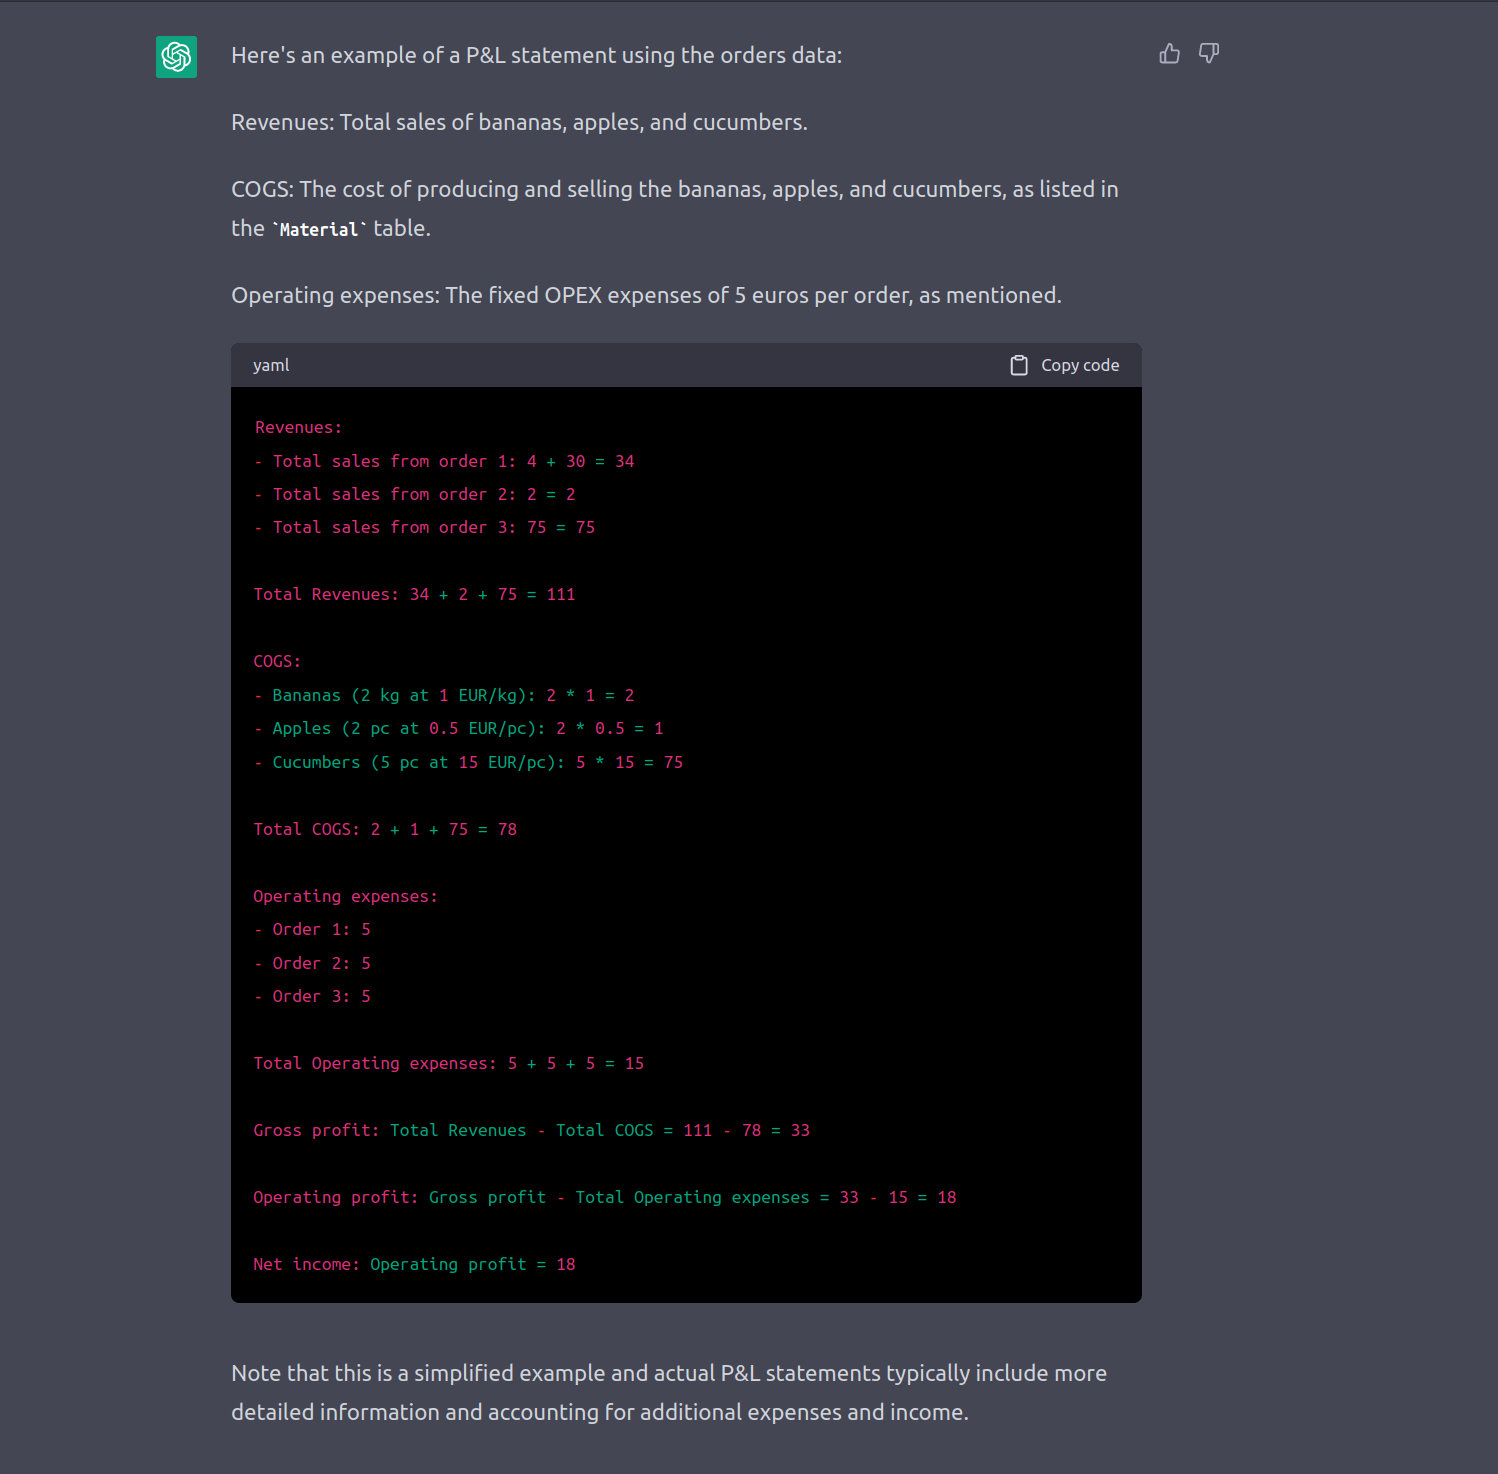
    I asked to get the P&L Statement – and got it.

    I tried without having COGS and OPEX – and ChatGPT complained – that is not enough to build a statement.

    What does it mean?

    Again this is a combination from world – knowledge and conversational knowledge. The interesting part is,that we moved from sales to finance and the data now is in a different context. Use of a database is not driven by its original design, but by the context and questions asked.

    Build and Application

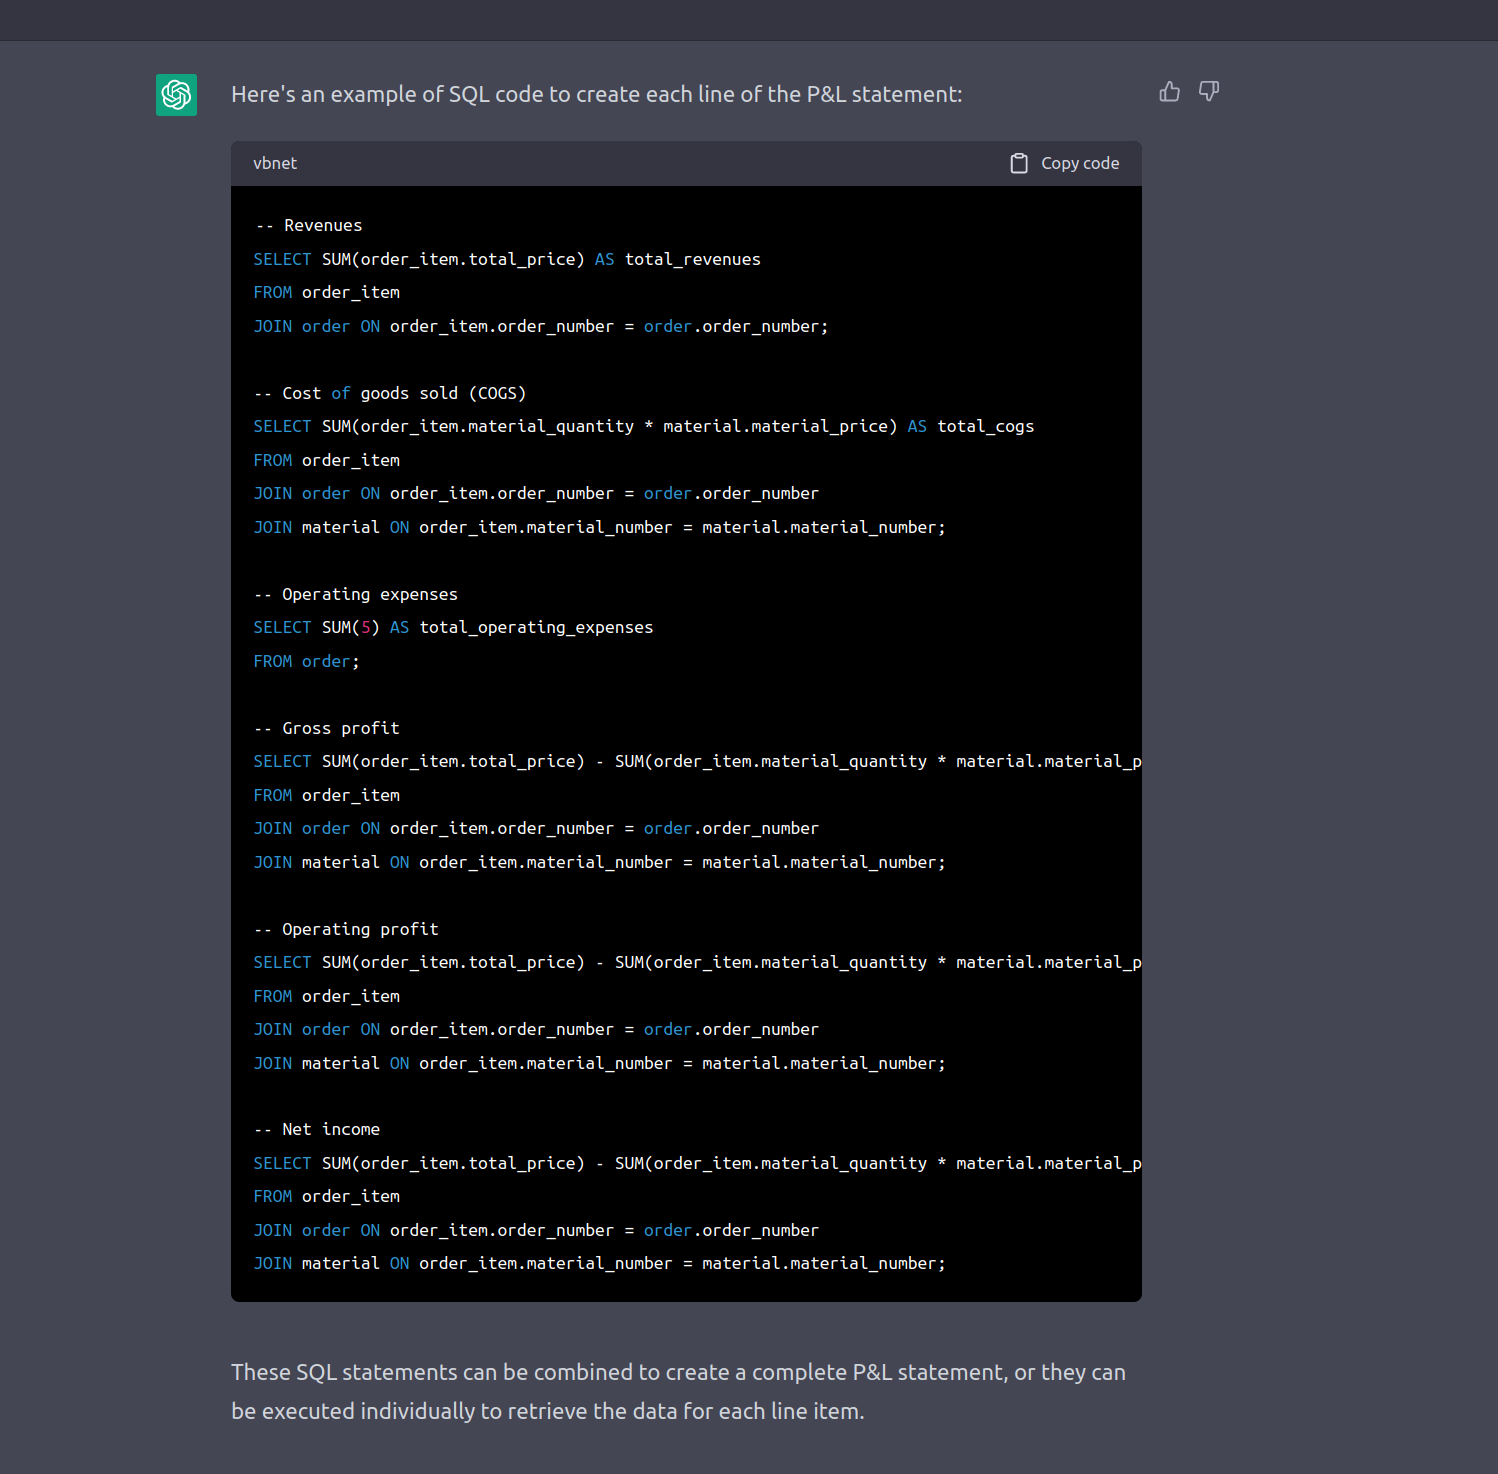
    Because conversational knowledge is restricted, its a good idea to conserve it in code/sql statements. I must admit I did not check those statements. I did checks for other scenarios and I found the quality pretty good, some joins would have taken me a lot of time to build.

    What does it mean?

    SQL Statements or programs can be generated by ChatGPT and it is really, really good in it. That statements can be seen as the persisted knowledge – I way to get the outcome documented and re-useable. A normal user query can be just executed by ChatGPT, something like an P&L statement should be based on a fixed, approved set of statements. Both ways are possible.

    work of dalle-2

    BIG CHANGE AHEAD

    Revolutionizing Data and Analytics: Envisioning the Future of AI that Combines General and Domain-Specific Capabilities for Unmatched Power”

    Sam Altman, the CEO of OpenAI, envisions a near future where custom-built/individual AI will be common and can have custom characteristics or knowledge.

    I envision a domain specific Data and Analytics AI enriched with common world knowledge, that consists of three components:

    1. Validated common world understanding (common layer)
    2. Validated subject matter expert knowledge (e.g. validated finance rulesets, US GAAP, SEC, Medical Research).  This rulesets could be tailored to a scope (research area) , a process (sales) or an application, like SAP BW or CFIN.
    3. Prompt Knowledge: Understanding of the specific details of a data lake or structure, which provides the overall framework for storing the data and gives direction to build the overall design. Similar to the prompt that has been used in previous examples, the prompt could also be the knowledge of a legacy system that needs to be used.

    Companies will start selling these AI as bundles, combining 1. and 2. and helping the customer with setting up the prompt knowledge.

    AI is already used in analytics, and it is already possible to ask questions in natural language that get translated into a dashboard, but I believe this will be on a different level.

    Different Way of Working

    Working with these platforms will be different, more flexible, and with less cost for changes and updates. It will require distinguishing between repeatable/fixed information still boiled in a fixed structure and a spontaneous query by a user.

    It is not clear how the future will be, but it will not remain the same. Given the current speed of development and the huge impact of AI in Data and Analytics, it will change, with new tools and new ways of using/accessing data.

    When making significant investments in Data and Analytics, this revolution should be kept in mind.